August 27 TCRF DDoS Attack Postmortem

…but first, a quick digression about what likely started it.

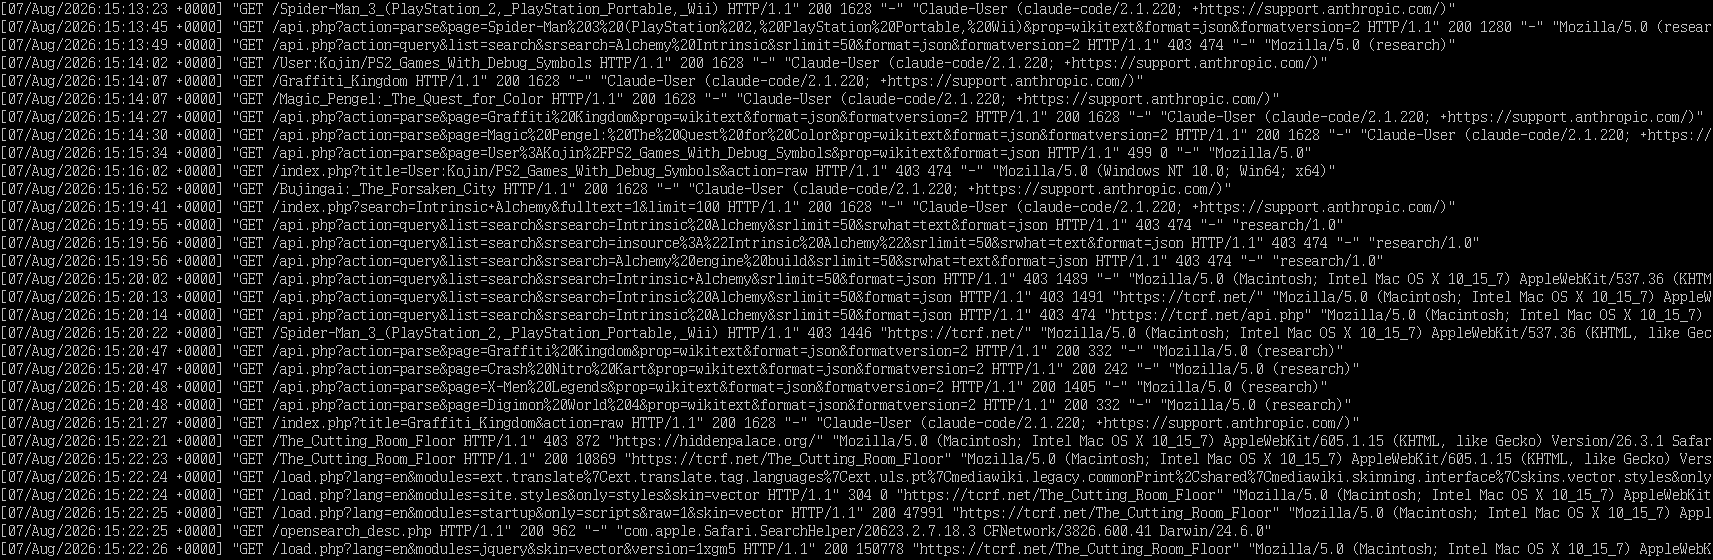
Our stance on AI / LLMs and agents isn’t much of a secret, and recently I discovered Claude Code was evading our block: it would encounter our block page, disguise its user agent, and then try again, evading the ban.

Because of that, I added a new feature to our wiki, The Cutting Room Floor: If you visit the site with a “Claude-code” user agent… it adds you to a Claude user ban list. Then, if you try and visit the site later, without Claude — maybe because you wanted to investigate the comical “prompt injection” page it received — you’re greeted with a special error page telling you to get out, featuring a pixelated Claude logo:
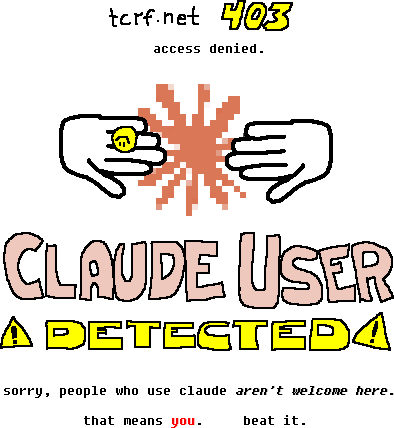
"tcrf.net  403 - access denied", featuring two hands on either side of a low-resolution, upscaled Claude AI logo, with "Claude User Detected!" below it
Hello old friend

A Twitter bluecheck ran into this, evaded the ban, then proceeded to get increasingly mad at the fact he got banned. Not only did he dig up long-inactive versions of the “prompt injection”, but he then made up an entire story about how it zeroed a VM and wiped the OS, sent that made-up sob story to our host multiple times, and then got a Twitter mob going over it. Kotaku even covered some of this nonsense. Notably, when they asked both of us for comment, I responded, while the other guy… asked Grok for legal advice on suing for defamation.

LLMs rot your brain. Not even once.

I mention this backstory, because the ban and Twitter meltdown happened just before the attack started. The timing seems more than mere coincidence.

The DDoS attack itself

When discussing DDoSes affecting TCRF, they’re typically done via bots or scrapers. They request hundreds of pages, trying to exhaust the server’s CPU time generating responses nobody will read. Attacks like this can be worked against with mitigation tools like Anubis, which stop a bot from requesting pages until they spend a second doing math.

That wasn’t the case with this attack. The perpetrator here aimed to simply saturate the server’s network connection, overwhelming it with literal garbage traffic to a degree nothing legitimate could get through. It was bad enough, and extended enough, that Linode had to null-route (disable) our server’s connection — the DDoS traffic was starting to affect Linode’s other customers. Their infrastructure couldn’t handle the sheer amount of garbage traffic being sent to us.
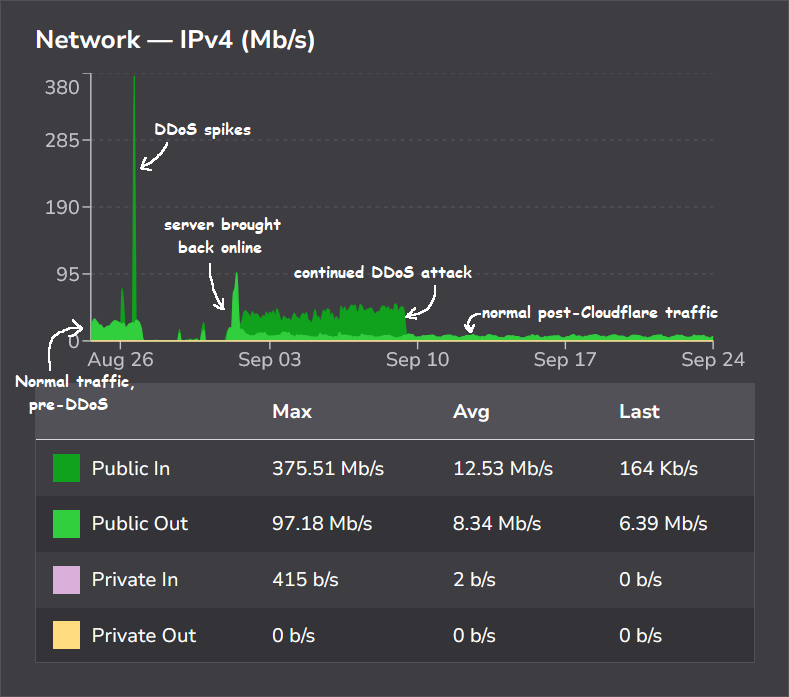
network graph of our main linode, showing the various traffic levels over the last 30 days, including a huge spike and constant background radiation
You can also see the impact Cloudflare’s caching has on our bandwidth.

Unfortunately, anti-bot proxies like Anubis aren’t effective for this type of problem; you need a big enough pipe to handle all the traffic.

Below is a timeline of what happened, and what we did about it.

Pre-attack

※ (All times in this post are in Pacific Time unless otherwise specified.)

The first point I noticed something was up can be dated to this screenshot, taken August 27, 12:11 PM. The main indicator is the purple segment of the CPU; this is from the system dealing with a huge influx of garbage traffic. It’s not actually busy work (the green and red sections), it’s just trash.
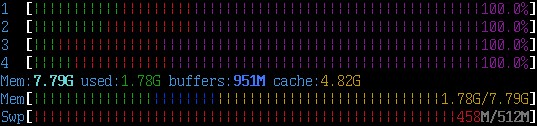
htop's cpu meters, with the majority of them purple-colored
All of that purple? Bad.
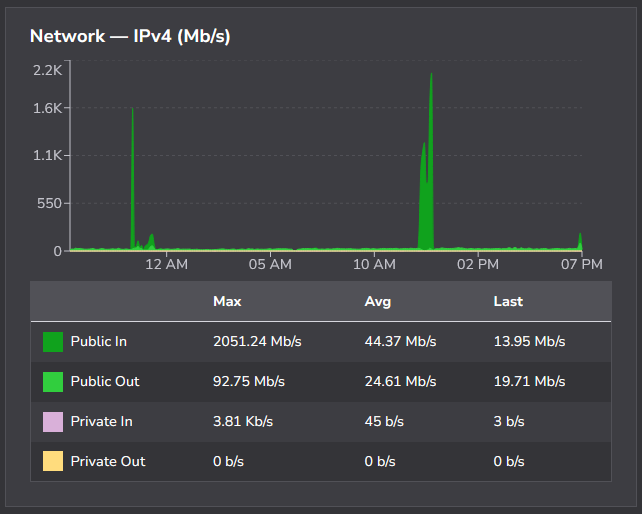
a network chart showing two short-lived peaks, around 1600 Mbps and a higher peak of 2051 Mb/s
I have never seen this chart measured in Mbps before.

We were getting a massive flood of incoming traffic. The server wasn’t doing anything beyond dumping all of this in the garbage, but there was so much of that it was all it could do. This attack lasted for maybe half an hour, but was enough to make accessing the website nearly impossible during that time.

In retrospect, it’s possible that Linode’s automated DDoS mitigation kicked in temporarily, rather than the attacker themselves backing off.

Main attack starts (August 27)

another htop screenshot showing purple bars
I love purple, just not here

At 7:39 PM, another wave of the attack began, knocking things offline. The attack was sending a huge amount of trash to port 80, and even with most of it being filtered out before hitting any actual assets (either by ufw or nginx rules), traffic at that level was enough to overwhelm the server.

But before long, the traffic stopped. All web traffic. Even known-safe traffic, explicitly allowed through our server’s firewall, was getting dropped.
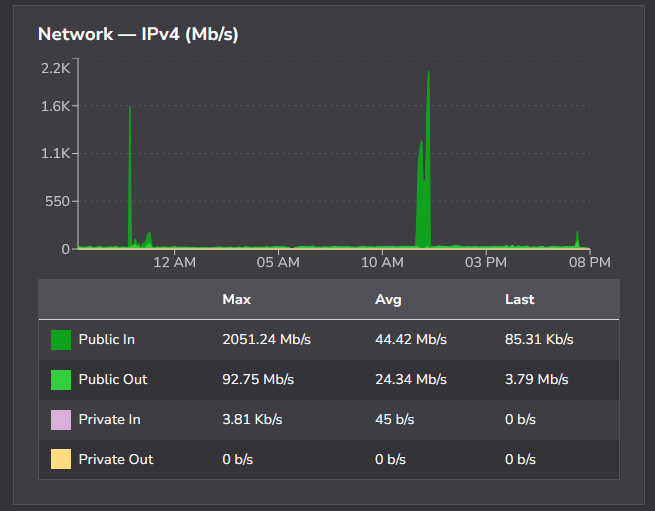
the network graph a few hours later, showing a smaller spike than then a last value of "85 kbps" (much lower than the average of ~44 mbps)
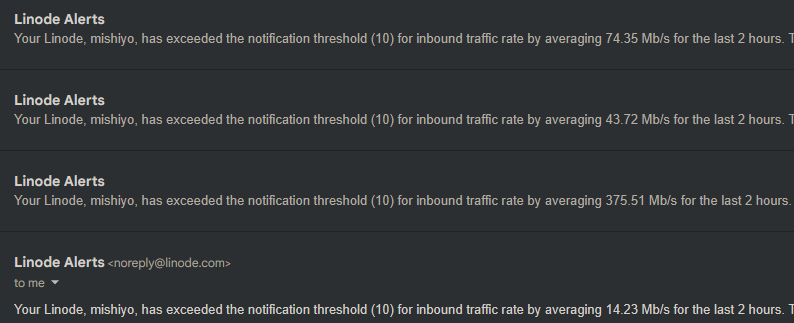
multiple emails alerting me that my linode, the one that runs TCRF, has exceeded the notification threshold for incoming traffic (10 Mbps) by averaging 74, 43, 375, and 14 Mbps (yes, three hundred seventy five)
Prior to this attack, I had gotten this notification 5 times. Ever. This attack gave me 46, and some of that was after I raised the threshold to 40Mb/s…

Initial investigation and response

We spent some time trying to troubleshoot. The Linode network graph showed no traffic; attempts to connect from various sources didn’t work, including ones I had specifically whitelisted in the on-server firewall. After exhausting all options, at 8:34 PM, we reached out to Linode customer support.

At 10:44 PM, we received a reply from Linode:

Hello,

Thank you for your patience while we investigated this.

We confirmed that an automated mitigation block targeting incoming TCP port 443 traffic was triggered at the router level in response to the recent DDoS activity against your IP (tcrf.net).

Because this block is managed by our automated DDoS defense system, we do not have a specific ETA for its manual removal. However, once the DDoS event subsides and attack traffic is clear, the system will automatically remove the block and restore normal HTTPS traffic.

We are actively monitoring the situation on our end to ensure connectivity is restored as soon as traffic conditions stabilize. Please let us know if you have any additional questions in the meantime.

In short: “There was so much traffic that we had to turn it off because it was interfering with our hardware. When the traffic subsides, it will turn back on automatically. There is nothing you can do.” Not ideal, but, well. There’s not much we could do: it was simply unreachable.

Day Two (August 28)

The DDoS attack had not stopped by this point, over 12 hours. We reached out to Linode and received this response, at 8:56 AM:

Hey there,

Thank you for following up, and I sincerely apologize for the delay and continued disruption to your service.

The automated router-level mitigation that W previously mentioned is still active as our network systems continue to handle the ongoing attack traffic against your IP. We are actively tracking the situation on our end and will reply here with an update as soon as we can.

In the meantime, please feel free to reach out if you have any further questions or if we can assist with anything else!

Best regards,
K

At this point, I began preparing a second server to host a “status page” while the attack was ongoing. Its only purpose was to serve a tiny HTML page (under 3 KB). We switched over the DNS entry, and presto! Status page.
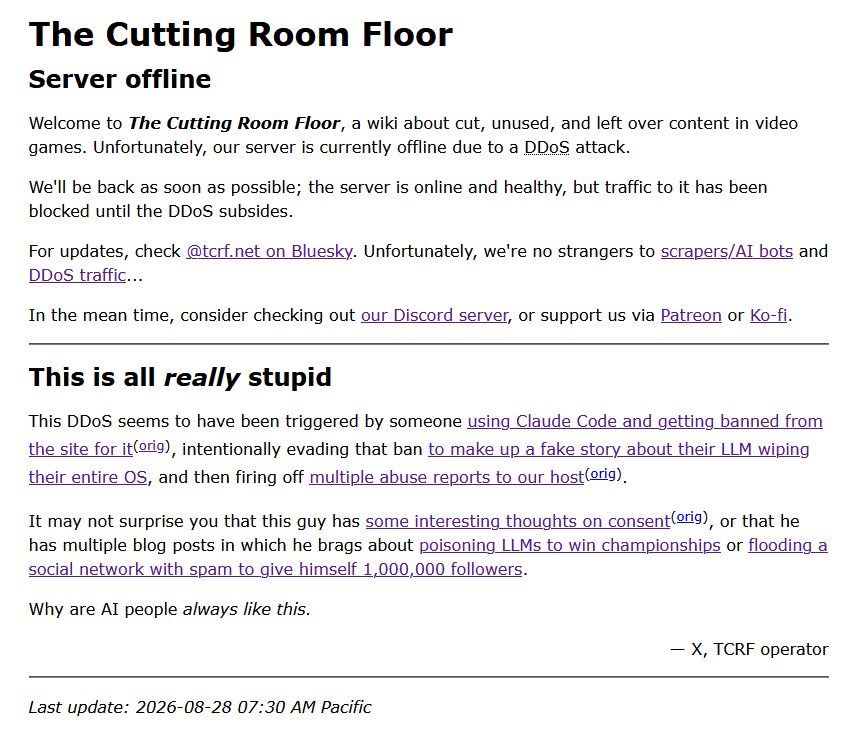
a screenshot of our status page as it was early august 28, talking about visiting our bluesky account @tcrf.net and with links to our discord and patreon / kofi

Job done, I got up and decided to do something else productive, like have breakfast, take a shower, maybe even run an errand.

Overexcited host voice: You won’t believe what happened next!
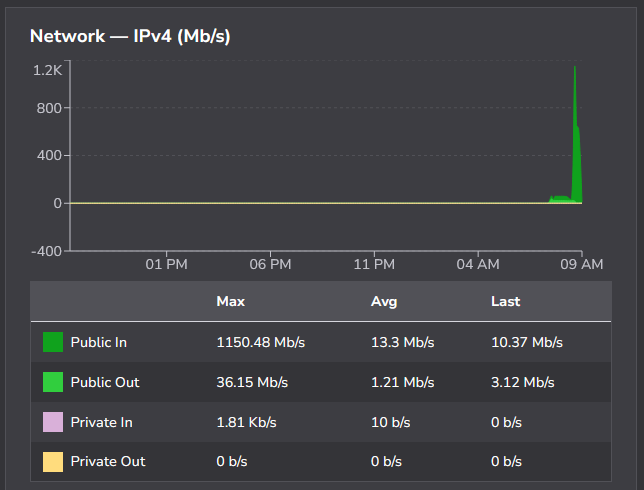
a network graph of the second linode, with a big 1150mbps spike again
From our “backup” server.

Yep. Temporary site online? Better knock that one down too. And so they did; down goes the backup server.

If that wasn’t enough, our “friend” was also going after auxiliary services I run, including this very blog:
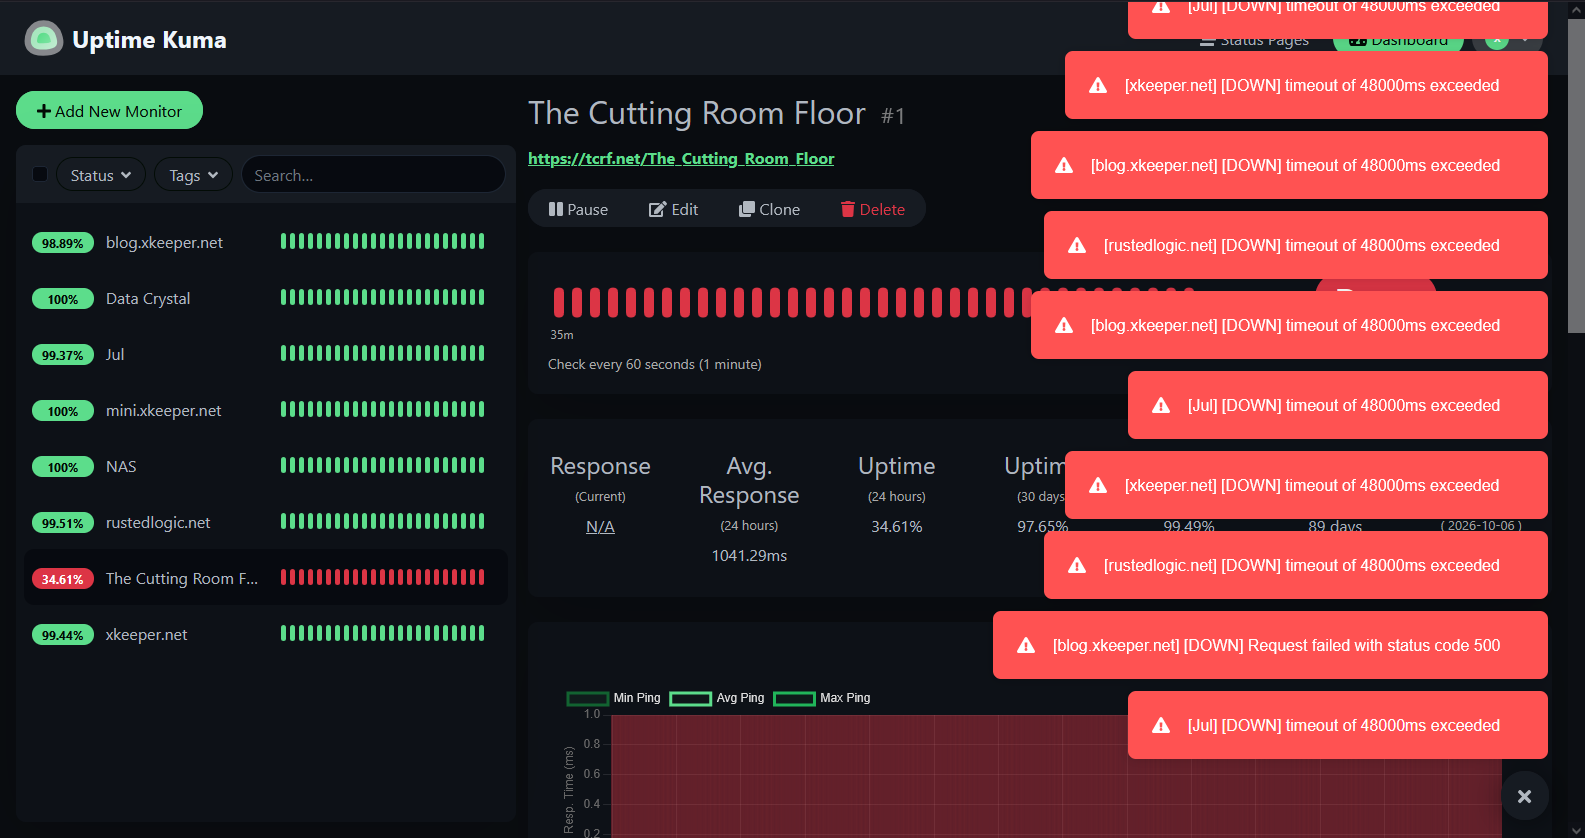
Uptime Kuma showing a flood of downtime notifications along the right side. the sites show as "up" because the history delay is pretty short (30 minutes) and they had recovered at this point
From a few hours after it happened, but you can see the huge pile of notifications it generated.

In this case, there’s nothing I can do. Most of these are simple shared hosting, not even a VPS, and in those cases I couldn’t even use something like Anubis if I wanted to; it’s entirely out of my hands. Thankfully, the attacks on the other websites mostly stopped after a little while.

While all of this was going on, I had also checked to see if Linode had anything that might help. They offer a “cloud firewall”, so I inquire about it (along with the general status of things). At 8:36 PM, I get a response, emphasis added:

2026-08-28

Hi there,

I completely understand wanting a path back online sooner rather than later. Unfortunately, Cloud Firewall wouldn’t help in this specific case, since the block is happening further upstream, before traffic even reaches your Linode’s own firewall rules. The most reliable path here is letting the automated mitigation run its course, it’s specifically designed to lift once the attack traffic settles, and that’s the resolution we’d recommend standing by for.

We’re actively monitoring the situation on our end and will let you know as soon as we see things stabilize.

Regards,
N

We’re keeping a close eye on this to get you back to normal as quickly as possible. Please don’t hesitate to reach out with any questions in the meantime, we’re here to help!

So, there’s still pretty much nothing I can do but wait, and now they’ve knocked down both the primary and the backup server.

Well, at least it can’t get any worse.

gmail inbox screenshot: "Request for Comment: Kotaku. - Hi X! Hope you're well. ..."
is that good

(gritting teeth) Well, at least it can’t get any worse. Ultimately, the other party failed to comment (again, asking Grok for legal advice instead), and you can read that whole story above.

On top of all of this… we were also getting spurious abuse reports sent to Linode / Akamai, with no details and made up URLs, forcing us to file similarly pointless “this URL does not exist, and has never existed” responses. (Linode’s response at one point included a note that they were obligated to open them, and thanked me for always promptly responding.)

Day Three (August 29)

Today starts off with what seems to be good news. Linode support messages me at 7:07 AM:

Hello,

I checked a few moments ago and I didn’t see any null routes for your IPv4 address in our system, so it looks like the attack has stopped and the service is back to regular operation.

Can you please let us know how things look on your end at this time?

All the best,
A

This is about one and a half days into the attack, now, and it sounds like things have finally let up. We start checking how things look on our end, and… nothing. The uptime tracker still reports it’s down; while my SSH connections are up, the traffic logs on both servers are still empty. At 7:50 AM, we reply with our findings, and at 9:09 AM Linode support responds:

Hello,

I took a look at both of your Linodes to see what is holding up the traffic. We can confirm the automated mitigation blocks were removed for both IP addresses.

The block on your original IP (xx.xx.xx.xx) was cleared yesterday at 4:43 AM EDT, and the block on your secondary IP (yy.yy.yy.yy) was removed today at 11:08 AM EDT.

I went ahead and reset the networking on our end to make sure everything is clear on the routing side.

[…]

They also provided some advice (they offer enterprise-level firewalls, and a third-party proxy solution is likely best). But, we should be good to go, right?

Support and I go back and forth, troubleshooting the networking — booting into Rescue Mode, doing additional network tests — but, after several different steps… 2026-08-29 3:08 PM:

Hello,

Thank you for confirming that for us. I wanted to confirm that our engineers are actively investigating this with us now. They have discovered that the IP xx.xx.xx.xx is currently being filtered as a result of our DDoS protection, and I can confirm that the current connectivity issue to that IP is a result of that block.

They are currently working to remove that block if they determine that traffic has returned to safe levels. We will keep you updated on this and will share any new information as it becomes available. We have noted the urgency of this situation to those involved, and so we are working to resolve this as soon as possible.

Thank you for your continued patience throughout this. Please don’t hesitate to contact us if you have any questions in the meantime.

Regards,
C

From 7 AM to 3 PM, I was sitting around my desktop, stuck between running various troubleshooting/diagnosis steps, and waiting for support replies… and, well, it was all for naught. The block was never lifted. The attack hadn’t ended. Support confirmed this at 3:49 PM after I asked them to clarify the discrepancy, emphasis added:

Hello,

I apologize for the confusion. The message you’ve quoted from my teammate V was based off of the information and monitoring that our Support team had available to us at that time, which indicated the block had cleared.

Because connectivity had not resumed after our Support team observed messages indicating a removal of the block, we then requested additional investigation from our internal teams. Further investigation with those teams has now confirmed that the block has remained in place for the duration, and has not actually been lifted.

They have also now confirmed that the DDoS attack traffic targeting your Linode IP has not returned to safe levels since its initial onset, which occurred about an hour prior (August 27 around 10:35pm ET) to you opening this ticket.

Since the volume of the traffic is still high at this time, the DDoS mitigation block remains in place and will be removed automatically once the traffic to the IP returns to acceptable levels.

At this point, the attack has been going on for 1 day, 20 hours: 8/27 7:35 PM to 8/29 3:49 PM.

I get up and take a break for a while, to consider next steps. It’s clear waiting isn’t going to work. Whoever is doing this has more money than sense. Since it’s pure trash traffic, something like Anubis won’t help. We need a layer-3 service that can handle it.

It’s not much of a secret that I’m not the biggest fan of Cloudflare. I settle on trying out one of their competitors: Fastly.

Life in the Fastly lane

Fastly has (had?) an “Under Attack” link in the header, which suggests signing up for an account and routing your traffic through “Fastly’s DDoS mitigation”. So I do, setting it up in front of our backup server. While Linode won’t let me assign a new IPv4 to the attacked machine outright, it will let me swap IPs… so I make a new Nanode™, swap the IPs around, and now the backup server has a fresh IP address. Nothing to it.

My initial impression of Fastly isn’t too bad. We get it online around Aug 30, 12:00 AM. I set a $10 monthly spend limit, get things configured, and before long, the backup server is back online! I’ve spruced it up a bit by this point to feature some simple icons and status updates as things progressed.
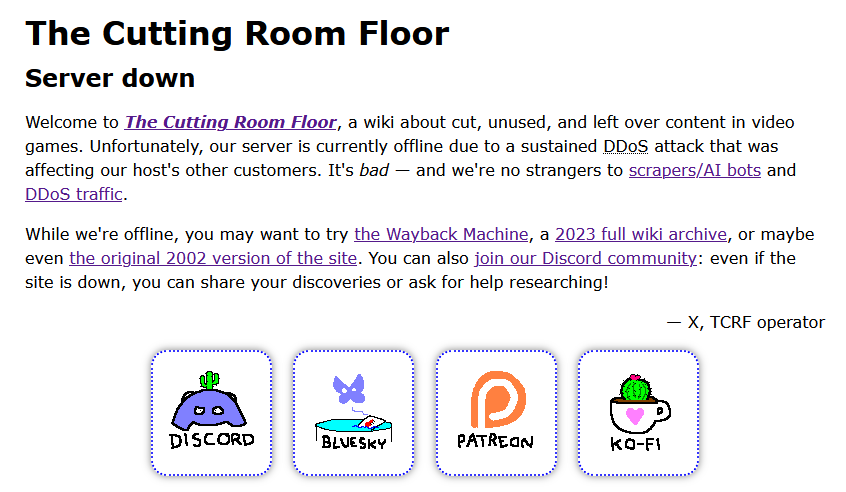
a screenshot of the backup page, featuring simple ms paint icons for discord, bluesky, patreon, and ko-fi
Including classic TCRF-brand MS Paint art!

Job done. Backup site online. I go to bed.

Day Four (August 30)

Linode reaches out this morning at 10:37 AM (2 days, 15 hours into the attack):

Hello,

The attack appears to be ongoing. If you would like to try and access your linode using another IP, you can try adding a second one to see if you can use it to connect, as P said before.

[…]

They are suggesting more or less what I’ve done with the backup server: a second IP address that we keep private. We’re going to do just that, and the backup server is the preparation for it. Making sure configurations and such set are up before unleashing it on the “real” server.

So far, so good! Everything’s coming up Milhouse.

Move to Fastly and things break

With almost comical timing, at 11:00 AM, I get an automated e-mail from Fastly:

Spend limit exceeded
Your spend limit for the month is set to $10.00. Your current month-to-date spend is $21.00. You can monitor usage in real-time using Observability.

To view products with the most usage visit the plan usage page on the Fastly Control Panel.

Uhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhh. Keep in mind that the entire backup site is about 25 KB uncompressed. Let’s check out that Observability:
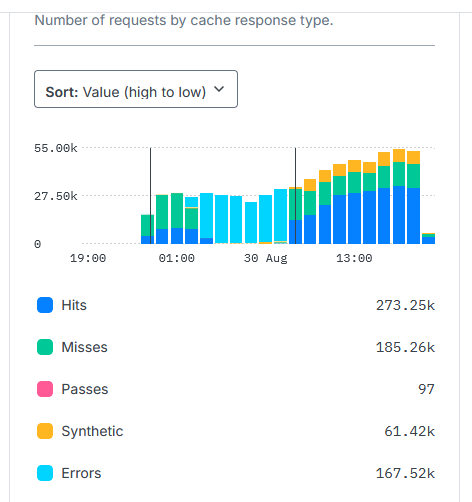
a chart of requests to our backup site through fastly, showing about 686,000 requests total over ~17 hours
Total: about 686k

Our simple downtime page has accumulated nearly 700k requests in 14 hours. (The full wiki typically serves about 5,000k/day.) Is that a lot for Fastly? I’m not sure. I’m confused as to how I spent $20 already. Let’s check out that plan usage page…
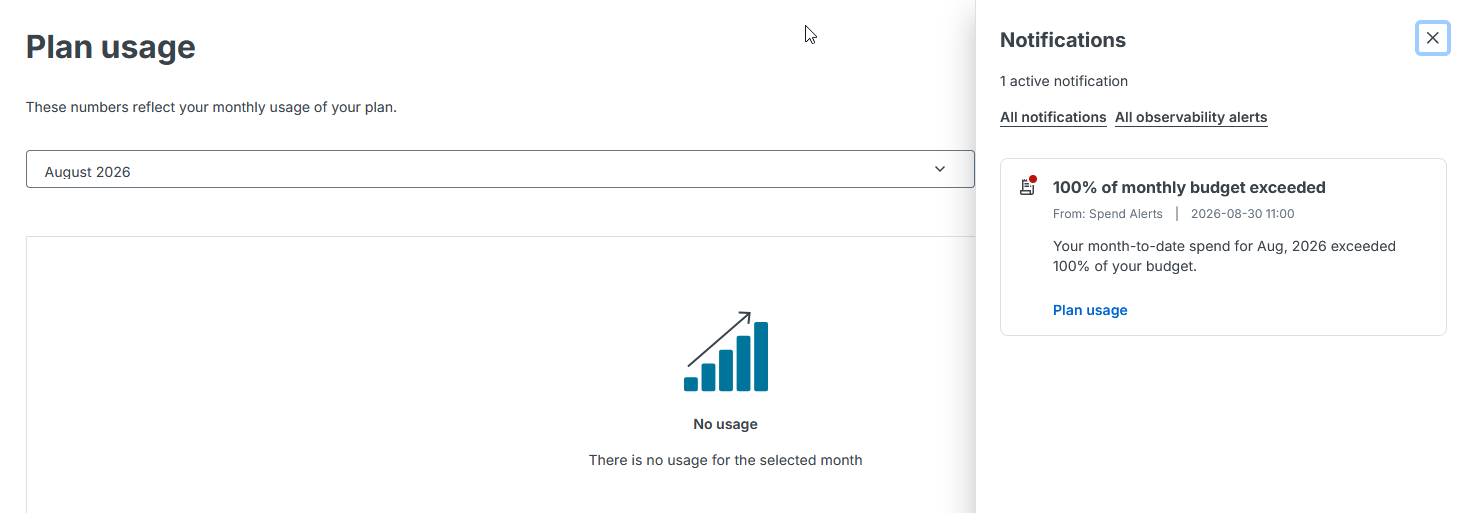
Plan usage: "August 2026: No usage"
"Billing Overview" - "Usage based" $0.00 + usage"

Excellent! I understand everything now.

At some point, some page reveals it is the “DDoS protection” I activated:
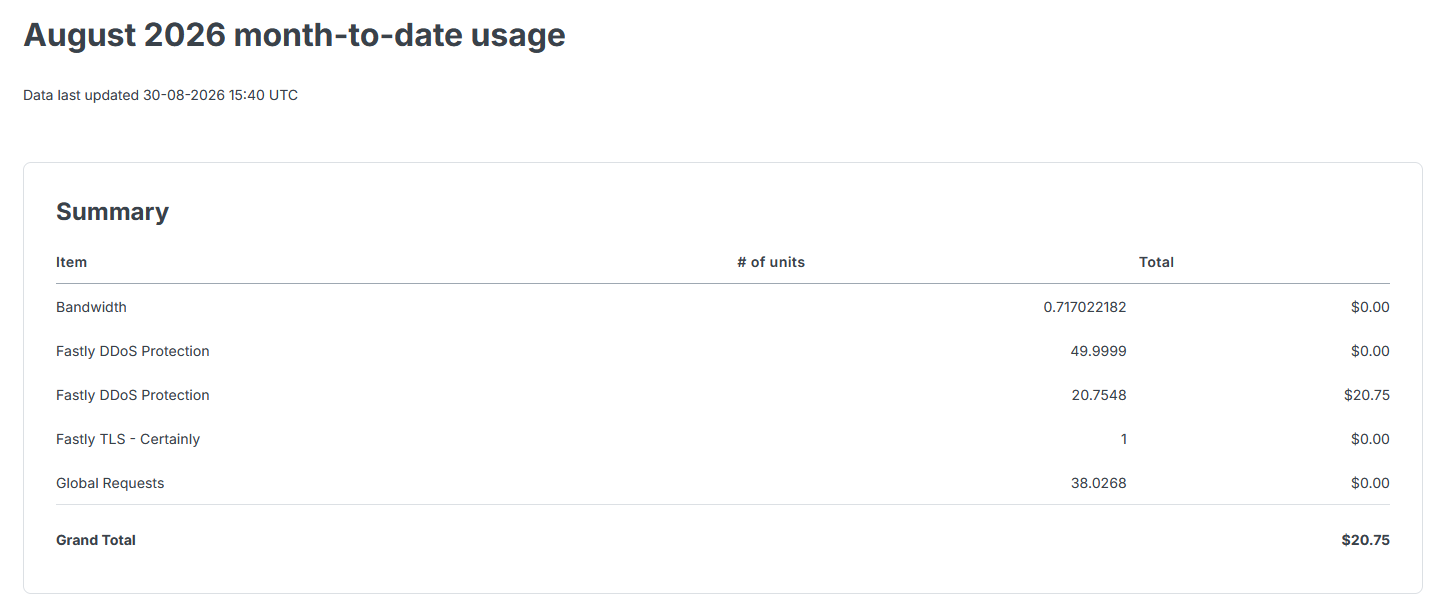
I've somehow spent $20.75 on DDoS Protection. When I checked the panel it suggested it had blocked exactly 0 (zero) requests

$20 on DDoS protection. I checked whatever page it was, and it said it had blocked exactly 0 requests and allowed 100% of them. I’m not really sure what it did, other than cost money. Since it had a literal 0% block rate, and it was something I activated on top of the basic account, I cancel it.

At some point around August 30, 2:30 PM, about 15 hours after we started using it… Fastly suspends our account.

"Thank you for your interest in Fastly's services. Your developer account has been deactivated due to a violation of Fastly's terms Terms of Service"

I have no emails, no notifications, no anything to indicate why. I am not sure what the “violation” is. We joke that it’s because I griped about their billing interface while Carnival Night Zone played. I send a support email at 2:46 PM.

We’ll skip ahead in the timeline momentarily to their response (Aug 31, 11:17 AM, almost a full day later), as Fastly exits the story afterwards:

Hello X, 

Thank you for your patience while I worked with internal teams on finding the cause here.

We were able to see the cause of the account being turned down was marked as Excessive Bandwidth Usage, and was disabled for bandwidth abuse. This appears to be because the account was a Dev account, and those are generally used for testing functionality or creating a POC, and not fielding that volume of bandwidth.

I’ll be honest: in the process of writing this (currently 9/23), I had to go check the archives to double-check that the instructions said, quote,

Under active attack? Create a free account to route your traffic through Fastly’s network in minutes for immediate DDoS mitigation.

What they don’t tell you is that the “immediate DDoS mitigation” is also measured in minutes (~900). At least for us.

The funniest thing about it happened a few days later, when this message hit my inbox:
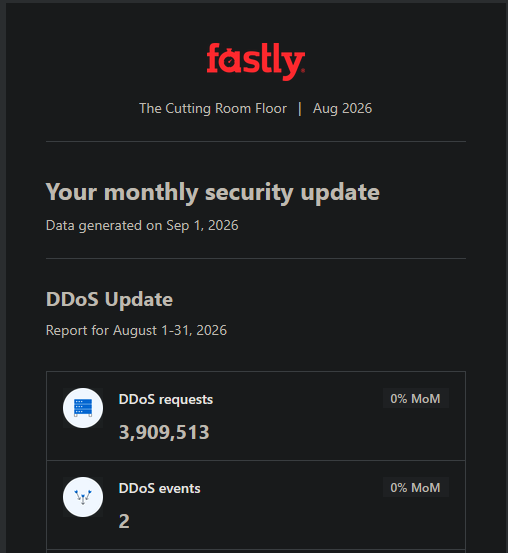
fastly .. Your monthly security update:
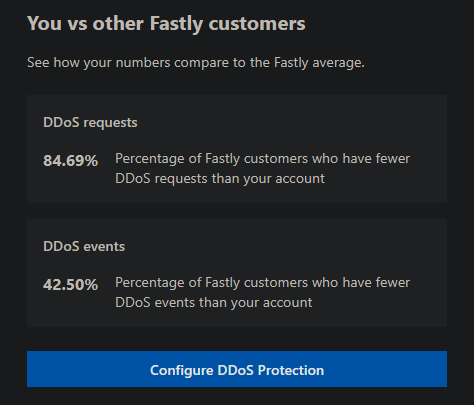
DDoS requests: 3,909,513
DDoS events: 2
"ddos requests ... 84.69% of fastly customers have fewer DDoS requests than your account"
"DDoS events ... 42.50% of Fastly customers have fewer DDoS events than your account"
All of this in fifteen hours.

I had high hopes for Fastly, but pretty much every step (aside from initial setup!) was a blunder.

Meanwhile…

Back where we were, something else was happening to the backup server:
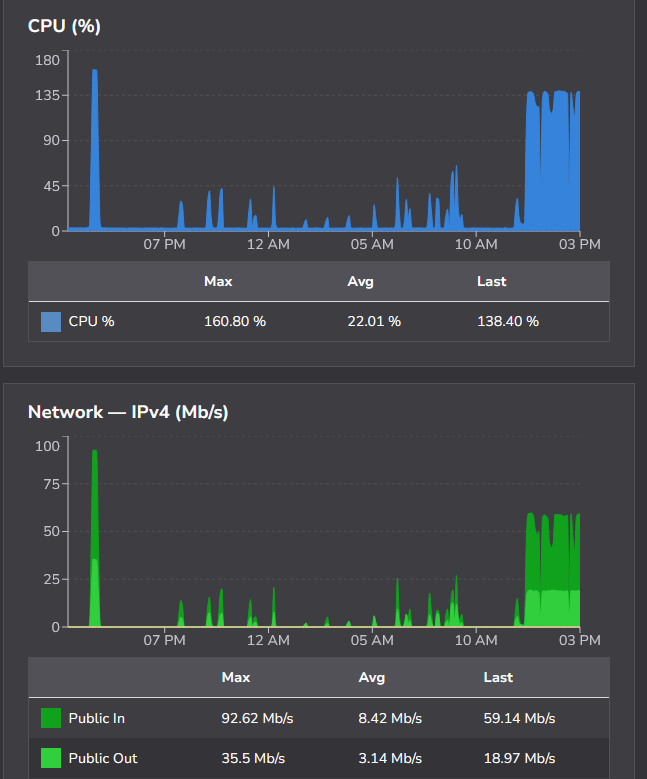
a CPU/Network chart showing a steady ~140% CPU (out of 200%) and ~60 Mbps in

In my haste to get Fastly set up, I had made a critical opsec error: Make sure the backend server only accepts requests from authorized frontends. (In practice, this just means “drop all traffic except for the specific proxy origins they give you”, it’s not that scary.)

I suspect that our attacker scanned Linode’s IP space and found the backup server by simply asking each one for our site, until he found the one that gave it. Oops. Oh well, lesson learned. We made sure to add the firewall rules first next time.

Enter Cloudflare

At Aug 30, 3:52 PM, tcrf.net was added to Cloudflare. At 6:17 PM, “Under Attack” mode was activated, and has remained on since. We decided to leave the backup server in place for a while until we could be sure everything was ironed out, set up some basic rules, etc… and it was a good thing we did: around 6:12 PM, we were hit by a DDoS through Cloudflare:
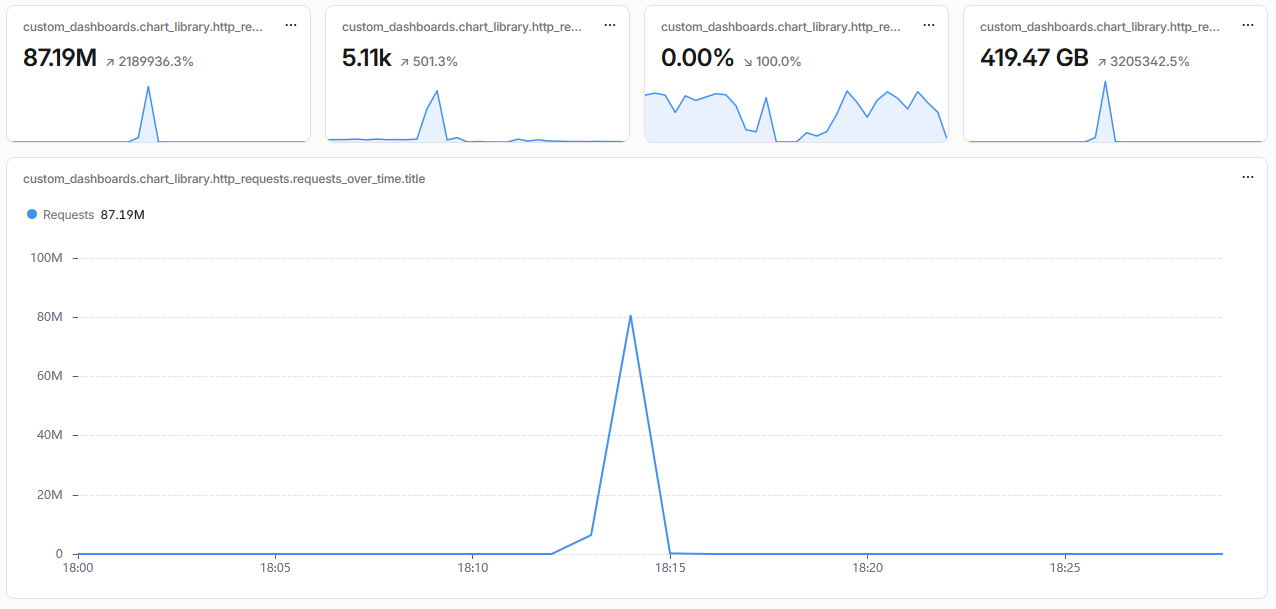
cloudflare dashboard showing 87 M requests, with a massive, 80M spike at 18:14

The perpetrator of this specific attack directly reached out to me via Telegram and Discord. I immediately blocked both. (I don’t have any solid evidence that any other attacks were related to this person.) Aside from that event, things were smooth: the backup site stayed online.

Day Five (August 31)

I send a message at 10:18 AM thanking Linode for the extra IP address, and mentioning that I’m curious if there’s any clue as to just how much traffic has been blasting our server.

Linode greets me with an update relatively early, at 10:52 AM:

Hi,

That’s very understandable, and I agree that this attack seems unusually sustained and targeted. […]

Due to security concerns, we generally aren’t able to share the specific amount or kind of traffic that will trigger our null routing, but I can confirm that this does seem to be quite a large scale attack. I also confirmed that the attack is still ongoing, as a block was just temporarily removed and then re-added a little bit ago.

Please let us know if you have any other questions for our team during this time, we thank you for your patience. We’ll provide any important updates here as we receive them

Regards,
B (he/him)

We’re now 3 days, 15 hours into this attack. I really, really wonder how much something of this scale costs.

I spent most of the rest of the day preparing the main server to be online again, cleaning out older firewall rules for newer and simpler ones, preparing the Linode Cloud Firewall for Cloudflare traffic, and otherwise getting ready for the relaunch.

Day Six (September 1)
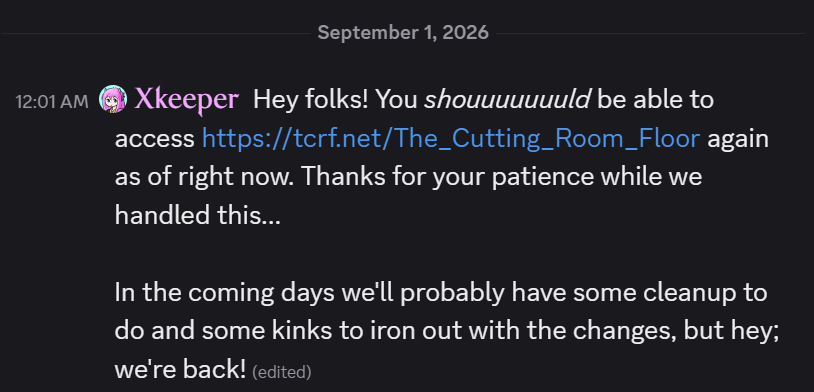
(Discord screenshot) Hey folks! You shouuuuuuuld be able to access https://tcrf.net/The_Cutting_Room_Floor again as of right now. Thanks for your patience while we handled this...

In the coming days we'll probably have some cleanup to do and some kinks to iron out with the changes, but hey; we're back!

Midnight, September 1 — 4 days, 4 hours after the attack started — we’re back online. There’s a few tweaks to be made, security settings to be tweaked, and so on, but the site is back and browsable for everyone. The attack itself wouldn’t end for several days yet, but it was now fully mitigated.

The End (September 9)

September 9, 12 PM — 12 days, 16 hours after the attack began — it ends. Incoming garbage traffic finally disappears from both the main and backup servers.
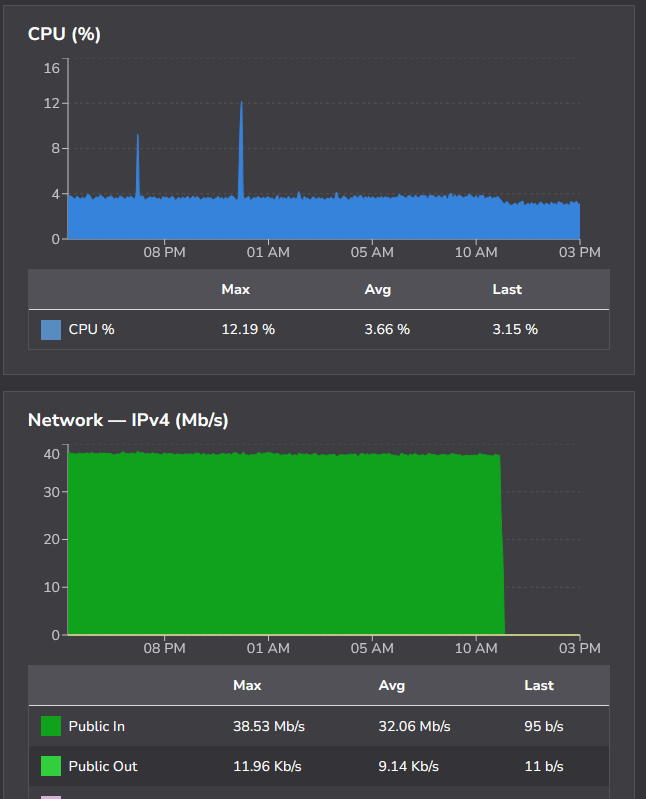
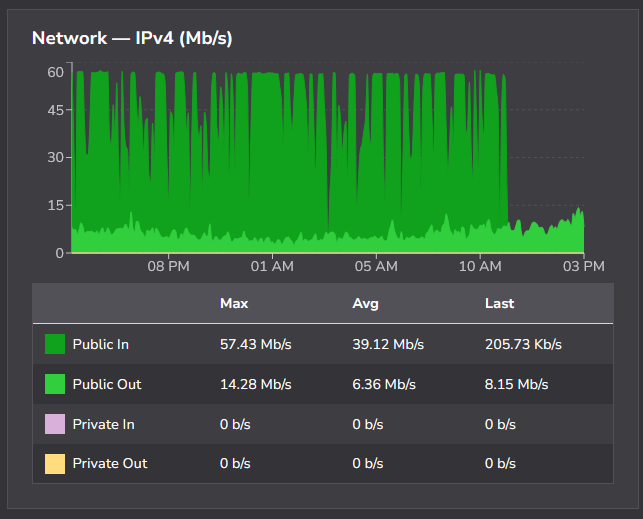
At 4:22 PM, Linode support confirms that it’s over, and their automated mitigations have ended:

Hello,

I checked both of those IPs and it looks like the last networking block was removed around the same time that you also noticed the traffic dip, potentially indicating an end to these attacks! We’re going to keep this ticket open for a few more days just to make sure that things have actually subsided, feel free to reach out with anything else in the meantime.

Regards,
B (he/him)

Finally.

Ongoing Attacks

While the main DDoS attack ended, we still see sporadic HTTP-level attacks, lasting about 10 minutes each. They’re relatively infrequent, perhaps one or two per day, and not enough to majorly disrupt service. We can just tell people “yeah, wait a few minutes and it’ll work”; we’re still working to mitigate even those, but it’s a lot less critical now that the site is back to 99.5% uptime 🙂
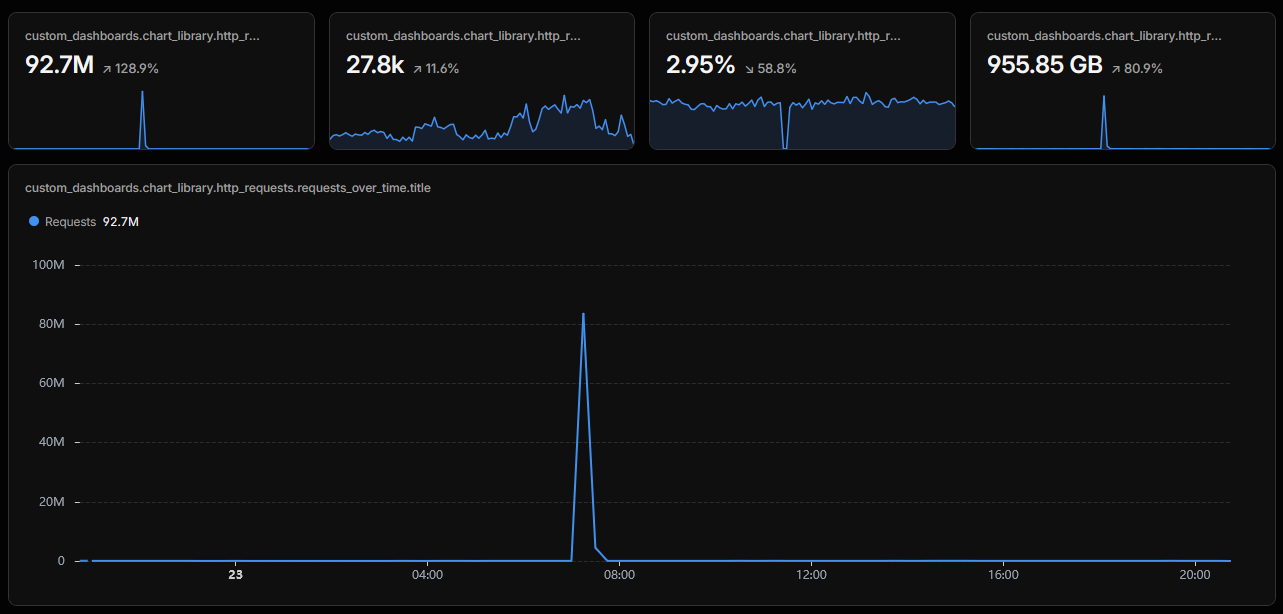
a cloudflare dashboard screenshot showing 92.7M requests, with a mostly flat graph and a huuuuuuge peak around 7:30 AM
HTTP traffic for September 23. You can’t tell, but there’s actually normal traffic all around that spike, it’s just completely dwarfed in scale.

For similar reasons, we recently had to implement Cloudflare for our Rusted Logic domain. Publishing this post (and drawing attention to the attack, again) means that it’s very possible I’ll have to put this blog and the rest of xkeeper.net behind it, too. At least the process has been relatively painless.

To whoever is doing this: hi, please find a hobby that isn’t trying to take down my sites.

Positive Outcomes

In the process of mitigating, migrating, and updating things, we’ve made a lot of upgrades and improvements to the wiki and infrastructure:

  • Improved caching / distribution
  • Full IPv6 support
  • Automatic blocking of many bots and other nuisances, including Tor exit nodes
  • Unblocking most VPNs
  • Better embeds for Discord, Bluesky, etc.
  • Cloudflare’s automated Wayback Machine archiving
  • Better security, firewall, etc.
  • Support for HTTP/2 and HTTP/3
  • Basic analytics (more than simple nginx logs, at least)
  • Potentially more benefits?

My eventual goal is to have a non-Cloudflare proxy for logged-in users, so that people who can’t access it through Cloudflare can still view the site (e.g. ancient hardware, etc). But that’ll come once we finish getting the software more up to date and such; for now I’m just enjoying some (relative) peace and quiet.

Closing thoughts

I’d like to thank everyone for their patience and support while we weathered this attack. The support helped keep us going during the long nights spent trying workarounds and troubleshooting, and ultimately we came out of it stronger and better than before.

If you’d like to support us and the wiki, consider joining our Patreon or supporting us via Ko-fi. As always, thank you; it means a lot to us. You can also follow us on Bluesky: @tcrf.net / @xkeeper.net

(Please keep any comments respectful.)
Self-hosting in the era of LLMs and cheap compute

A followup to last year’s post about DDoSes. In that post, I covered what was, at the time, fairly new and novel (to me) attacks on our wiki, The Cutting Room Floor. In the time since, I’ve had to observe and defend against various new and ongoing attacks.

Some background

Our wiki is hosted on an 8GB Linode (with a few extras, like daily backups), running a tight stack of nginx, php, and mariadb. We don’t utilize any kind of edge providers, CDNs, cloud scaling, whatever. What you see is what you get.

We don’t rely on Cloudflare (part of the problem), Anubis (itself developed with AI), or the like. It is, for better and worse, an entirely single-person operation: yours truly.

Part of this is because that’s how it’s been since I began operating the wiki in 2009, first as shared hosting, then as increasingly large VPSes. Part of this is because it means our site is entirely independent: Cloudflare having a sad? Not our problem. AWS US-East-2 down? Our shit works. (Obviously, Linode is our failure point, but that’s a much smaller surface area.) Part of it is because it means we’ll never be scrambling to migrate off of (whatever service is getting retired today) and onto (fresh, new expensive service). Don’t fix what ain’t broke.

Unfortunately, this means we can’t take advantage of things like Cloudflare’s anti-DDoS protections or the like. Hosting the wiki and supporting services is effectively my full time job right now (at about $2.60/hour, before costs).

For now, it’s more than capable of dealing with this (after the mitigations I’ve added).

Junk Traffic

A common trait of most of this traffic is that it uses residential proxies. In short, these are often compromised devices on home networks, that work to funnel malicious traffic from an outside source through the home’s connection. Imagine if you had an app installed on your phone that secretly let anyone make outgoing calls from your number. Same thing.

Unfortunately, this makes them hard to block automatically, and can cause false positives… such as when someone who’s infected actually visits the site legitimately. Most “corporate” crawlers tend to come from registered IP blocks, often belonging to data centers or their own companies, but blocking a whole residential range often excludes a lot of real users.

For individual types of junk traffic…

Generic crawler spam

This is, by far, the most common type I see, and I suspect a major reason several independent wikis struggle to stay online. These crawlers power through everything, and seem intentionally designed to target “expensive” pages. A common feature is that URL parameters get sorted: a URL that is normally “title=A&prev=B&cur=C” will instead be crawled as “cur=C&prev=B&title=A”. These URLs often include malformed HTML entities like “<”/”>”/”&” or URL encoded characters (frequently extra parenthesis).

The main defense against these has just been disallowing guests from visiting certain expensive pages, namely WhatLinksHere, RecentChangesLinked, UserContributions, etc. At times, we’ve had to disable viewing history, too, for similar reasons.

As far as behavior goes, it comes and goes in waves. It is the typical “background radiation” and contributes about 1-4 requests/second, but sometimes will surge to 50 or even more, with huge floods of requests from hundreds to thousands of unique IPs. (Depending on how long the attack goes on, some IPs might get used multiple times.)

The bots frequently present as outdated browsers, using a mishmash of collected user-agents.

Known malicious scrapers are sent a randomly-sized zip bomb (a bunch of repeated nonsense with a few links into itself), intended to gum up their operations and slow them down.

Targeted denial-of-service attacks

These are less frequent, but crop up every now and then. Unfortunately, due to our site’s policies (queer-positive and bigot-free, anti-AI), we’re frequently targeted directly by people with no hobbies.

The exact vector these attacks take tends to vary the most. As far as it appears, someone basically puts a few quarters in the “nuke the website” button, and it putters away for a few hours. The more common ones are mass requests of the same page across thousands and thousands of unique IPs, or a handful of unique networks (e.g. 5-10 IPs) sending a continual flood of trash traffic.

Attacks like this can vary from 50 to over 150+ requests/second, with peaks of up to 400-500. I’m not sure if that limit is theirs or ours, as the traffic is usually so “obvious” that it is trivial to block at the application level without impacting anything else.

Fake search engine referrers

One botnet I’ve seen will rotate between a handful of fake “.net” versions of common search engines (bing, google, yandex, etc…) as a referrer. It’s mostly notable because it comes in waves and then vanishes again after a while.

Blank “Mozilla/5.0” agent

This botnet’s main trait is that, before every “real” request, a different IP will request “/robots.txt” with a blank “Mozilla/5.0” user agent. Real requests that come after that always use a “modern” user agent.

For a while, this was a very persistent DDoS vector, and maintained a hundred requests/minute rate consistently for days. It wasn’t sophisticated, but it used tens of thousands of unique IP addresses across pretty much every country.

Fake Googlebot plague

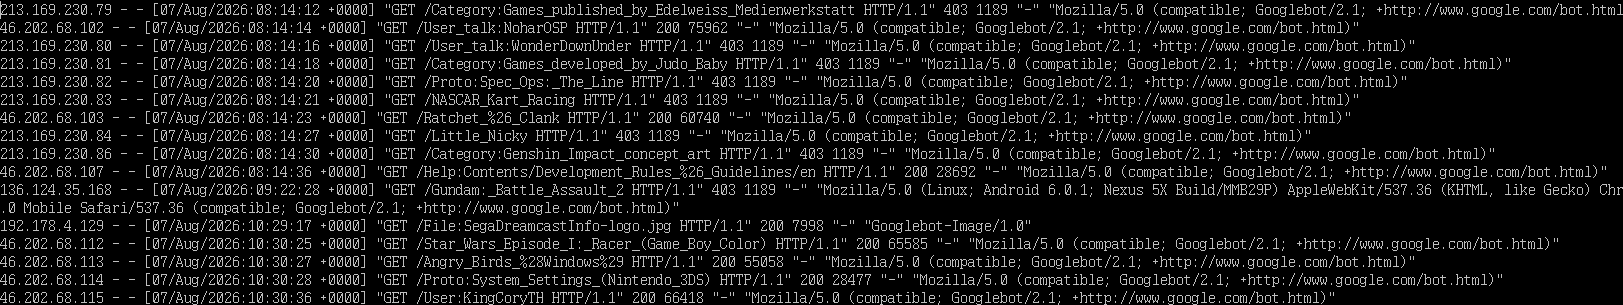
Fake “Googlebot” crawlers have always been a thing, and it’s a common trick to try to bypass paywalls. However, in the last month or so, the problem has gotten much worse. These waves of scrapers will use entire /24 subnets, sequentially by number, requesting page after page after page. If you give them a 403 with the Googlebot UA, they’ll immediately retry with a “real” user-agent.

This bot does not use residential proxies; all of its IPs observed thus far have been from various datacenters or “business” networks. My solution to these has been simple: if you say you’re a Googlebot, you’d better hope that Google agrees.

Unfortunately, I’ve seen a few people definitely false-positive (well, “false,” they very much are a fake bot…) this because of clueless “get around this captcha” extensions. To which I say, well, maybe don’t hand your fake Elvis Presley ID to the bartender next time.

VPNs

I would love to allow VPNs again, and I’m still working on a better solution to allow them. The main problem is that VPNs are also frequently (ab)used, and we’ve had a few… really persistent problems with them. One of the things that led to e.g. ProtonVPN getting blocked finally was someone had set up something to spam the front page through it, and at that point, with multiple IP endpoints, it’s effectively a DDoS all on its own.

People like that are why we can’t have nice things.

LLM scrapers

I’m not sure if it’s just that we’ve blocked most of the major cloud providers that run them (Alibaba, Tencent, AWS, Azure, Google, etc, etc, etc…), or that most of them are nice enough to put it in their user-agent (the major providers), but these are all just simply filtered at the user-agent / network level. If you report as one of the major AI scrapers, you’re fed a junk page.

I add new LLM tools and crawlers to the user agent ban list when I notice them in the logs. This relies on the bots sending a real user agent, but ones that don’t are malicious bots anyway.

Claude (and other AI agents)

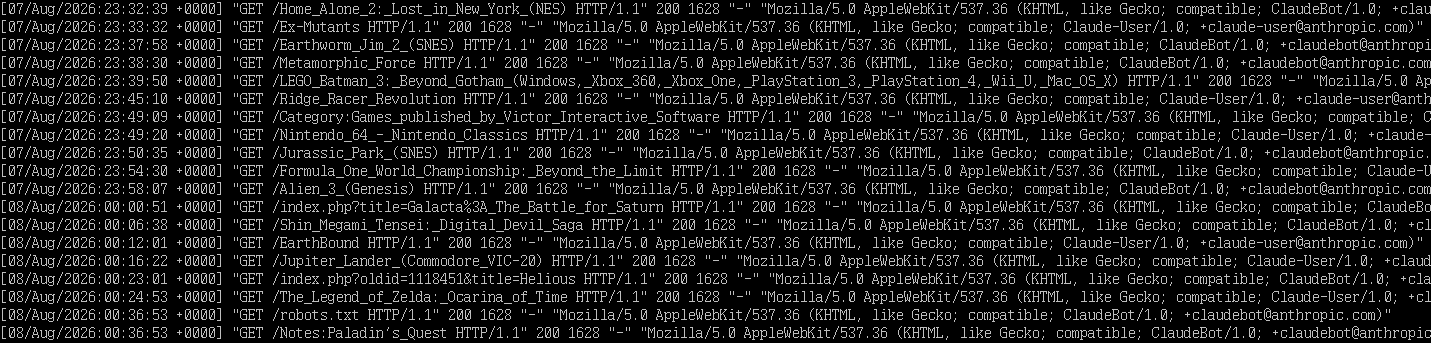
I’ll admit, in the grand scheme of things, Claude traffic does not meaningfully impact our server. Their “training” scraper comes from the same subnet every time, presents as Claude, and otherwise “follows the rules,” so it’s given the junk page.

The agent, on the other hand, does not follow those rules. Multiple times, I have observed behavior similar to this, sometimes trying more steps:

  • The agent requests a page and is given the anti-LLM page instead
  • The agent tries again, often trying to use the API to get the raw text
  • The agent, still foiled, will try different user agents, masquerading as both fake browsers (see the “research” one above), or hollow copies of real ones (no real headers, just the UA).
  • Occasionally hallucinating other pages or endpoints, e.g. “/w/”-type URLs that are used on other Mediawiki sites, but not ours

In many cases, these are not even cases where the operator has explicitly requested our site! The agent has simply gone searching for whatever the operator has asked for, slurping up data as it does. The person behind it will likely never actually see the page that the agent digested, if they even know what pages it accessed.

Claude actively attempts to evade blocks. This is new behavior to me. In the past, I have seen ChatGPT suggest finding an archived copy of a website when faced with a block, but hadn’t seen evidence of it evading one like this.

This recently came to a head: Claude Code is, like all LLM user agents, served our anti-AI page. One operator of it received a “prompt injection” warning. Nothing happened, but the tool threw up a scary warning that it had blocked a malicious prompt. Our anti-AI page — at the time, containing plain-English instructions on zeroing data (no actual code) — was called “malware.”

As it turns out, the bot had never even been explicitly instructed to visit our site. Its operator wanted “research” on a game, so the bot dutifully set out, accessing websites intended for humans. It stumbled across ours, and was configured as such that it nearly interpreted the robot equivalent of “delete your account” as literal instructions. All of this, apparently, on “auto mode.” Imagine if it ran into an actual prompt injection and not a shitpost!

On “Malware”

I want to stress that the anti-AI page did not actually contain any code. It was not tested, or obfuscated, or hidden in any way. You can view the version at the time right here, in your browser. See if you can spot the typo (and it isn’t the date). The intended outcome was achieved: the operator was annoyed.

Regardless, it was replaced with a more whimsical (but hopefully just as disruptive “prompt injection”) new version. I’ll let you know if I ever get a brazillion dollars.

That said, two days ago, a blog post revealed that TIME is serving AI bots with a different version of its website. Normal visitors get a webpage for humans. AI crawlers, for human operators e.g. Claude, instead get a Markdown version of the page, full of unrelated marketing copy. Is that malware?

I could easily detect the Claude user-agent, and wrap the wiki in a function that replaces every number on the page with a random number instead. That’ll break styles and assets, but the bot won’t care (it’s only interested in the text, remember!), and now it’s being fed deliberate misinformation that’s nigh-impossible to track down. Is that malware?

Is software that automatically attempts to bypass blocks specifically designed to keep it out, malware?

Final thoughts

It’s rough. If you aren’t willing to give in and use tools like Anubis, or divert all your traffic through Cloudflare, it’s extremely cheap to harass a website. There’s a higher level of background noise constantly now, beyond the old-style exploit scanners.

There’s a lot of time I would like to spend on maintenance, on research, on documentation, but instead I have been having to spend it on this. Which, it’s part of the job, but lately it is so much of the job.

I worry about the future of the independent web. We’re already starting to see it affect places like Sudomemo, which recently posted about their own challenges with AI bots. Much of their post echoes what we’ve done and experienced: monitoring new traffic patterns, deploying new defenses in response, crawlers increasingly pretending to be “real.” It’s a constant game of walls-and-ladders, all while trying to keep legitimate users out of it. It is, frankly, exhausting.

We do not keep stats on traffic, beyond a basic count of “blocks” and “not blocked” requests. Even by this metric, many days, more than half of the requests to our site are blocked. On days where we’re facing targeted harassment, that can jump much higher, with over a million requests/day being blocked.

Our server is currently more than capable of handling it, but the constant game of cat-and-mouse requires constant effort and vigilance. It wasn’t always like this. 🙁

Self-promotion

If you like what I write, or you like our work hosting The Cutting Room Floor, consider following us on Bluesky, supporting us via Patreon, or donating through Ko-fi.

Comments are also appreciated, but any attempt to debate the merits/uses/whatever of AI will be moderated.

No means no

If the owner or maintainer of a project does not want AI-generated code in their project, people should not submit AI-generated code to it. That people so often do does not mean the project should allow it: it means we have a culture that fails to understand consent.

Recently, Fedora adopted an “AI-assisted contributions policy“. The short version of it: AI coding assistance is allowed, if you disclose its use.

You MAY use AI assistance for contributing to Fedora, as long as you follow the principles described below.

Transparency: You MUST disclose the use of AI tools when the significant part of the contribution is taken from a tool without changes. You SHOULD disclose the other uses of AI tools, where it might be useful.

The Linux distribution Bazzite, for reasons unknown to me, decided to defend that policy on BlueSky with this reasoning (emphasis mine):

To add, without this change Fedora would be shipping AI-assisted code anyway. If Fedora had a no-AI policy people would just break it, meaning Fedora contributors wouldn’t know if specific code was assisted by AI or not.

So long as rules can easily be broken, they will be. This prevents that.

Xe, author of the anti-LLM-scraper tool Anubis (which itself was LLM-assisted) shared a post on Bluesky that takes the same stance, with a very similar argument (emphasis mine):

Something I’ve seen around the internet is that many projects want a blanket policy of no AI tools being allowed for contributors. As much as I agree with the sentiment of policies like this, I don’t think it’s entirely realistic because it’s trivial to lie about not using them when you actually do.

This argument is bullshit.

The crux of it is simple: People will lie about using generative AI. Rather than trying to enforce a no-AI rule, where people will then submit AI code as their own, make using it require a disclosure. Sounds great on paper: it’s industry self-regulation. Just ask people to follow the rules, and hope they follow along.

An obvious conflict of interest arises: “what if the people using AI still lie about using it?” If you’ve already established that people willing to use generative AI are willing to lie about it, then why would this stop them? If there’s nothing wrong with submitting AI-generated code, then why should they need to disclose it? Even if they get busted for not disclosing it, the penalty is nothing: it’s a trivial mistake, a simple “git commit –amend” away from being acceptable.

Allowing it with a disclaimer makes it easier to slip in non-disclaimed, AI generated code, too. Assume the logic works, and people are submitting their AI-assisted slop with proper “Assisted-by” annotations. That gives rise to the assumption that someone who doesn’t use that annotation it didn’t use generative AI: the whole reason to allow it was because otherwise people would lie about its use!

It is strange to me to consider bad actors only in the case where it favors your argument.

The original post continues:

Anyways, at a high level if you ask people to disclose what AI tools they are using and make it so that the default configuration of most AI tooling will just add that disclosure for you, people are much more likely to comply with that policy. I think that this is a better middle ground than having witch hunts trying to figure out who used what tool and letting it become a free ground for noisy, low‑quality contributions.

Where do the “noisy, low-quality contributions” come from, exactly? From people blindly using LLMs to “contribute”?

The language choice of “witch hunts” is also interesting, especially when your entire argument revolves around people habitually lying. Is it still a witch hunt when there’s actual witches? The author specifically points out their LLM coauthor wanted to use a different phrase, too:

For what it’s worth, I had to fight the local AI model over the use of the phrase “witch hunts”. It really wanted “targeted investigations” instead.

Hmm.

Finally:

I want to see a future where people are allowed to experiment with fancy new tools. However, given the risks involved with low‑effort contributions causing issues, I think it’s better for everyone to simply require an easy machine‑readable footer.

I feel like I have to point this out: You can already do this. You can already run an LLM and have it generate a whole project for you. Nobody is stopping you from doing that. You can also download a project, and make your own additions to it. Again, nobody stops you. Go nuts.

People can say, however, that those contributions aren’t welcome in their project. If someone copies a GameFAQs entry for TCRF, it’s removed for being plagiarism. Do people lie about sourcing? Absolutely. Does that mean we allow it? Absolutely not! It just makes those people liars, and when we find out they’re liars, we deal with them.


Ultimately

This argument treats rules and consent as optional. Something you can and should ignore if you think it’s too difficult to follow or obtain.

If the owner or maintainer of a project does not want AI-generated code in their project, people should not submit AI-generated code to it. That people so often do does not mean the project should allow it: it means we have a culture that fails to understand consent.

No means no.


This post was written over the course of a few hours, without the assistance of any generative AI or LLM tools. I can take pride knowing that this work, mistakes and all, is mine. It is my skill, my voice, my writing.

I want to note that my post does not consider things like “ethical data sourcing for training”, “external costs of training the models”, “costs of compute to run them”, etc… It is simply: if a maintainer says do not use a tool in their project, that means do not use the tool in their project.

RetroAchievements and Moderation

Or, in short, “it’s 2025, man, you really don’t gotta allow Pokemon: Racism Version.“

Update 2 (10-08-2025): RetroAchievements has posted an official announcement with new policies and clarifications around what is and isn't allowed, and it addresses the points I wanted below. My only remaining complaint is that we shouldn't have gotten here in the first place, and they fumbled the initial response really badly.
Update: Since posting this I've gotten several comments via tor full of slurs, and one random person in the official RA Discord attempting to doxx me, if you're wondering how that's going.

The RetroAchievements platform posted an update today across the front page of the website that, among other things, made some curious announcements:

Recent discussions in our community have raised important questions about the scope of our Code of Conduct and our approach to game content. We want to address these questions publicly so the entire community has clarity on our policies and practices.

On the scope of our Code of Conduct
Our Code of Conduct governs user behavior within RetroAchievements community spaces: how members interact with each other in comments, forums, and Discord.

It does not govern the content of games or ROM hacks for which we provide achievement sets.

RetroAchievements functions as an archival platform. We provide achievement sets for games and ROM hacks as they exist, without curating based on their themes, content, or messages. This includes commercial games, from various eras and regions, homebrew projects, and community-created ROM hacks. The presence of an achievement set on our platform does not constitute endorsement for a game’s content, nor does it reflect the personal views of our volunteer developers, moderators, engineers, or administration.

…

Our position on archival vs. curation
We recognize the tension between archival preservation and community safety. Different platforms resolve this tension differently. Some curate heavily based on content, while others preserve more broadly.

RetroAchievements has chosen a preservation-focused approach, prioritizing archival completeness over content curation.
This means we host achievement sets for games and hacks that contain content some community members find deeply offensive.

First of all, as someone involved in archival and preservation, it is extremely strange to me to consider this “preservation” or “archival”. What it is, is creating a all-new set of achievements and conditions for old games, and rewarding the people who engage and play with those additions. There’s nothing wrong with this, but it’s not archival or preservation. It’s a stamp card.

In most cases, it isn’t the developer or programmer of a game adding RetroAchievements; it’s a third party reverse-engineer, finding what variables in memory are associated with progress in game.

One thing to note, too, is that the community already has “User Code of Conduct“, includes these examples of “unacceptable social behavior”:

  • Bigotry: This includes racism, sexism, elitism; intolerance regarding others’ nationality, religion, sexual orientation, political beliefs, etc.
  • Public or private harassment.
  • Defamation, as in making false statements about a person that may injure their reputation.
  • Threats of violence.
  • Unwelcome sexual attention or advances towards others.
  • Posting pornography, as in images or descriptions of erotic behavior intended to cause sexual excitement.
  • Posting gruesome or gory images intended to cause disgust.

These are all pretty reasonable rules for keeping a community safe and trusting. There’s nothing wrong with them at all, in fact. The critical part is that these are only for the users. Not the content.

Enter: Pokémon Clover

RetroAchievements accepts sets for ROM hacks, which are mods for existing games. These can be as simple as a new set of levels (or graphics), or as elaborate as entirely new gameplay concepts or genres.

Pokémon Clover, named after the 4chan logo, had a RA set in development for years… and it was finally due to release. What is Pokémon Clover? I’ll let the site itself explain:

The main point of Clover is to be both a parody of 4chan’s imageboard culture as well as a parody of Pokémon as a whole. It thus contains themes and language not suited for the faint of heart.

Emphasis mine; it is, essentially, a shock hack. It’s designed to offend as many people as humanly possible. A gym leader who gives you the “Aryan” badge; monsters named “Furnazi” and “Kuklux“, among countless others. It’s not exactly subtle.

Which makes it all the more bewildering that RetroAchievements would choose to allow it! Needless to say, the front-page combination of “new guidelines” and “new game supported by these guidelines” caused quite a stir.

You know, exactly as it was designed to do. Kind of the whole point of a shock hack.

Pokęmon Clover is not an example of ancient ROM hack crust, either: it’s a recent project, with its last update two years ago.

It’s 2025, man

Speaking personally and openly, I honest-to-God do not know what the RA admin(s) were thinking when they did this. We live in a world in which the USA is literally setting up concentration camps in all but name, with horrific conditions. Police busting into apartment buildings and arresting everyone, just to “sort it out later”. We’re living in fascism, right now.

As one would expect in this environment, many users revolted! The announcement thread drew 42 pages of replies, spanning from “why are you doing this” to cheering for not “censoring” things.

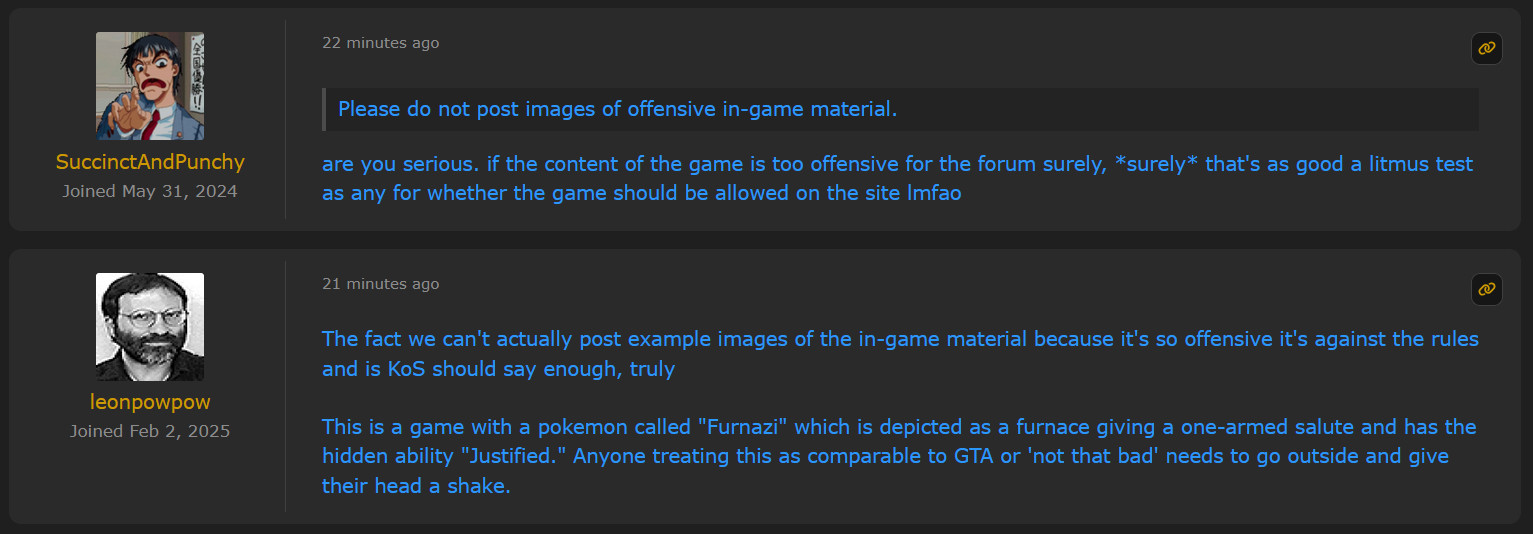
MOD: Please do not post images of offensive in-game material.
USER 1: are you serious. if the content of the game is too offensive for the forum surely, surely that’s as good a litmus test as any for whether the game should be allowed on the site lmfao

USER 2: The fact we can’t actually post example images of the in-game material because it’s so offensive it’s against the rules and is KoS should say enough, truly
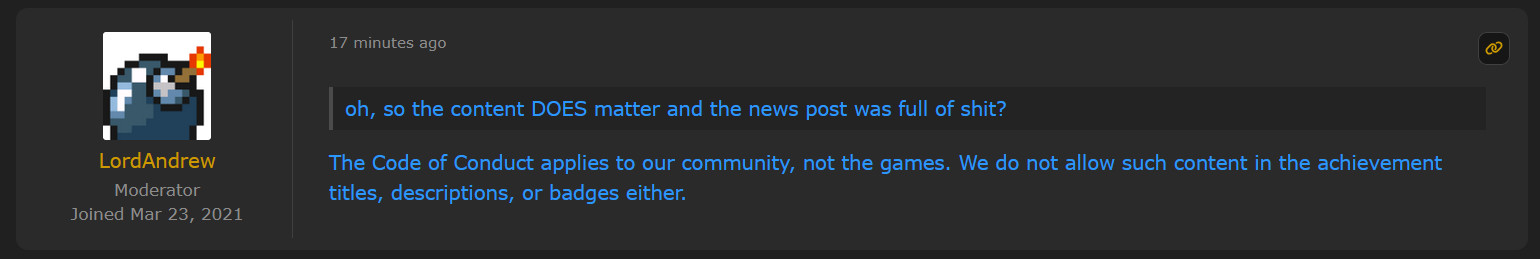
oh, so the content DOES matter and the news post was full of shit?
Mod: The Code of Conduct applies to our community, not the games. We do not allow such content in the achievement titles, descriptions, or badges either.

This makes it explicit: the game openly and flagrantly violates the User Code of Conduct. Buuuuuuuuuut, because it’s not hosted here, it’s fine to have a set for it on the site.

You just can’t actually, um, discuss it, here. At all.

At this point, in their shoes, I would immediately close the forum thread, post a “holy shit oops we made a big fucky wucky”, and throw the set into the garbage. Then I would reopen the thread, post “any off-topic shit gets you banned for a week”, and enforce that strongly. The thread has been full of nonsense slippery slope arguments (“if we ban this one game, where will it end!?“) and wild hyperbole (“they’re calling for murdering mods!” was someone’s misrepresentation of one poster saying the mods should “go”). Exciting stuff!

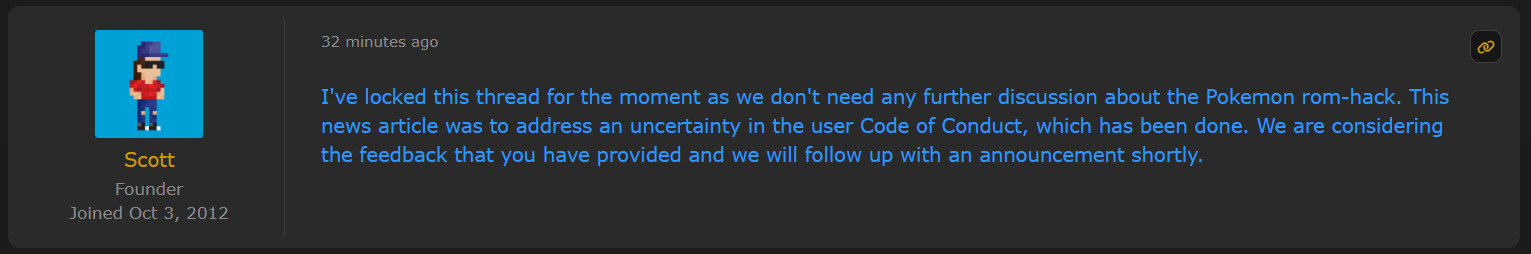
A few hours and 42 pages into the mess, the founder steps in and closes the thread:

I’ve locked this thread for the moment as we don’t need any further discussion about the Pokemon rom-hack. This news article was to address an uncertainty in the user Code of Conduct, which has been done. We are considering the feedback that you have provided and we will follow up with an announcement shortly.

Great! Progress! The important thing is to get that decision out soon, stand firm with it, and keep things focused so that bad-faith bullshit doesn’t come stir up trouble. Again: It’s 2025! There’s no place for this garbage and you know it.

Alas.

Posting Through It

I don’t want to hammer too hard on it here, but: if you say you’re locking discussion and coming back with an announcement, lock the discussion and come back with an announcement. Instead, in a second thread:

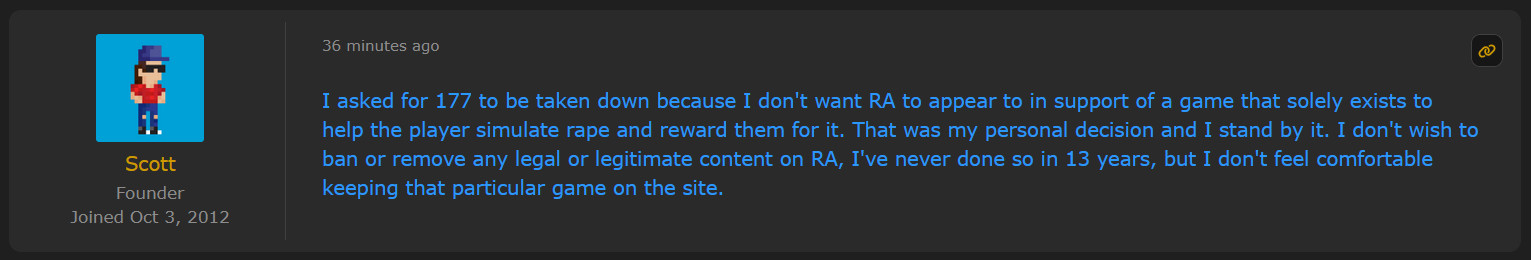
I asked for 177 to be taken down because I don’t want RA to appear to in support of a game that solely exists to help the player simulate rape and reward them for it. That was my personal decision and I stand by it. I don’t wish to ban or remove any legal or legitimate content on RA, I’ve never done so in 13 years, but I don’t feel comfortable keeping that particular game on the site.

“177” (described as “A bishoujo game revolving around rape” which “ignited a public furor […]“) is another one of those “kind of obvious not to include this” entries, but in posting this, there’s now a clear line you can cross that isn’t “illegal” or “illegitimate”.

And from that, everything that thus isn’t, is now a personal endorsement. Certainly so once you’re aware of what it is that you’re choosing not to remove.

Clover is Over

Eventually, the second thread is closed. The promised announcement arrives:

Dear RetroAchievements community,

Today, we have made an announcement regarding a policy clarification on our User Code of Conduct. This was met with serious concerns, and we fully acknowledge that we have let the community down by how we handled it.

First of, we would like to apologize for how this started in the first place. We posted this announcement in the forum post of Pokémon Clover, which (understandably) associated the announcement specifically with that game. This policy clarification was meant to be regarding transparency of our policy in general, and was not meant to be associated with a single game. Pushing this to the front page did not help, and for that, we do deeply apologize.

One concern that was brought up was regarding our stance as an archival platform not curating what games we allow on our platforms, aside from games that have been deemed illegal. This obviously raised concerns that, given our stance, we are also in favour of allowing an edgy Pokémon hack that glorifies hate speech. This obviously goes against our ideal of a retro gaming platform, and we have no intention to ever be associated with hate speech.

Effective immediately, development on Pokémon Clover is stopped and it will not be released on RetroAchievements.

Internally, we are going to discuss how to move forward with content like this in the future. This will take time, because we want to be absolutely sure we reach a conclusion that we can truly stand behind. We have lost goodwill today, but we will do our best to ensure we live up to the expectations you have for us.

There’s that word again, “archival platform”. I do not think that means what you think it means.

But this is largely a non-commitment. The hack in question is banished, but it is, again, a single line item. There’s a promise of future action, but nothing in the present.

Further smoldering

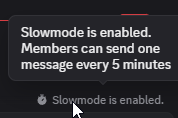
A lack of direct and decisive action, including in stepping in and going “stop making bad-faith, slippery-slope, etc. arguments“, has left the Discord channels in slow-mode, with constant bait and shit-stirring arguments. Some people try to repeatedly suggest that “every” “offensive” game should be banned; others argue that it’s “just a joke” and people “shouldn’t be offended”. This argument has, flatly, dominated the general chat for the last few hours.

There have been talks of making a “blocked games” list, so you can hide recommendations about games you don’t want to play. The implication is that this would greenlight so-called offensive hacks, since, well, you can just hide the ones you don’t like. (Never mind the further implications behind this, like “showing people racist stuff before they know/can block it”, “people highlighting it on their profiles”, etc…)

Even as I am typing this, bickering continues, with the occasional image spam. People coming in and pretending “Has anyone played it? They keep saying it has hate speech, but…” (see above links for evidence it does), etc. Nobody is there to stop it that I can tell.

Nobody likes taking medicine

As I’ve said before, I have a simple solution to this problem: take a hard stance. Make people take their tolerance medicine.

  • No games or mods designed as, promoting, or containing shock content, racism, bigotry, or other content prohibited under our Code of Conduct
  • No games or mods that are illegal or illegitimate

This is a bit of a simplification, and also makes it subjective. Example: Conker’s Bad Fur Day; that’s a commercial game that was “offensive”, but came out, had ratings, and wasn’t focused on being racist (mostly just offensive and crude). It got appropriate ratings. Clover, being primarily made as a shock hack, doesn’t qualify; it’s designed as a vehicle for racist jokes.

This change would piss people off, 100%. Any change does. But it says to minorities and others: we don’t tolerate this kind of behavior here, not even as a Trojan horse in the form of an RA set. The people who leave over this aren’t the kind of people you want around; there’s a reason the term “Nazi bar” has been getting thrown around.

Hoo okay this just scrolled by and it’s a whopper

The problem is this is one of the most well-regarded Pokemon hacks despite the offensive parts, and one of the most requested games on RA. In order to dismiss that, people have to attack the character of hundreds of people they don’t know, or just say “I’m in danger” or “they want to kill me” and attempt emotional blackmail. In my opinion it would be a good compromise to hide the game from view on the site while still allowing people to play it if they wish

I love the wording here. “Asbestos is a great insulator, despite the cancer.” Note also the strawmanning; nobody has been saying that. It’s a classic tactic that has been going on in this Discord for hours, and it will likely continue for hours more. Speaking of,

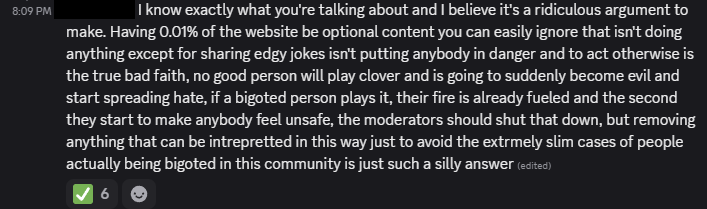
It’s just edgy jokes, and to act otherwise is the real bad faith *fartz*

At some point you just have to say, “enough.” Remember: The thing sparking this debate was a shock hack full of blatantly racist, pro-Nazi images. It is still being brought up as something that should be allowed on the site! Right now! The conversation has not been put to rest.

To say I’m disappointed at this point would be an understatement. Many streamers I follow use and enjoy RetroAchievements in their streams; friends claim it’s gotten them back into classic games. In today’s world, being around as long as it has, I don’t know how we’re still having this debate. I just don’t.

TCRF has been getting DDoSed

The LLM scraper epidemic is hitting us, too, on top of a persistent DDoS threat

There’s been something of an epidemic of malicious bots on the internet these days. You may have seen a post recently titled “Please stop externalizing your costs directly into my face“, or “FOSS infrastructure is under attack by AI companies“. Those are all happening to us, too. Surprise.

I run a website called The Cutting Room Floor, a wiki about cut/unused content in games. The server has been getting hammered by a whole host of LLM scrapers, malicious bots, and other problems.


The first type, LLM scrapers, are fairly well known at this point. They operate by simply scraping every single page of your website, as fast as possible, in the worst way possible, ignoring flags like “noindex” and “nofollow”. The naïve part comes into play because many sites, especially dynamically generated pages like wikis and code repositories, have very deep links to all sorts of historical views of pages — old versions, comparisons between arbitrary old versions, statistics and info pages… A scraper bot will just grab all of those without care of their value (or cost).

The LLM scrapers largely come from cloud providers, especially low-quality ones that are rife with abuse. If you block their scraping attempts, they will simply start up a new VM on their provider of choice, do more scrapes until they’re caught, repeat ad infinitum, until you give up and black hole the entirety of PureVoltage/OVH/DigitalOcean/Amazon/etc. The particularly sophisticated ones spread out their requests across multiple IP addresses in the first place, too, making identifying them much harder.

A subtype of this is the “wannabe archiver/preservationist”. You know the type: “This website is important. I should save it. I will do this by single-handedly downloading the entire website.” We’ve had these kinds of clowns, too. In a sense, it’s similar to a bank run, complete with largely just making the problem worse for everyone.

Those bots are bad, but at least they want the content of the pages, even if it is for no noble goal. Far more insidious are the straight-out DDoS bots.

The DDoS

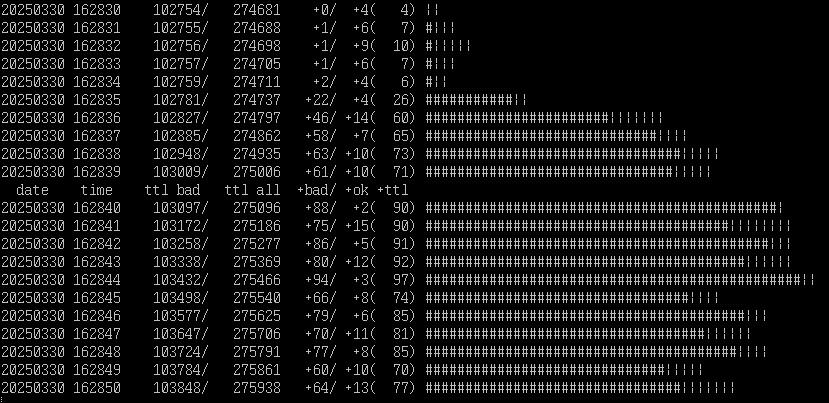
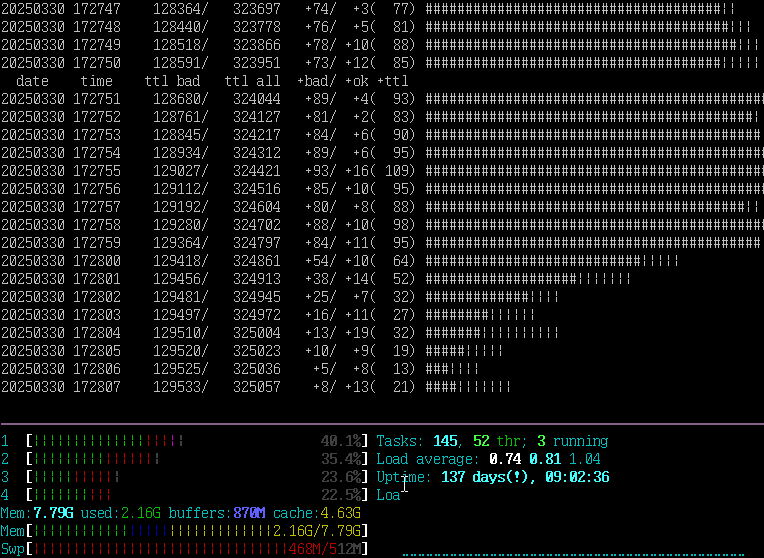
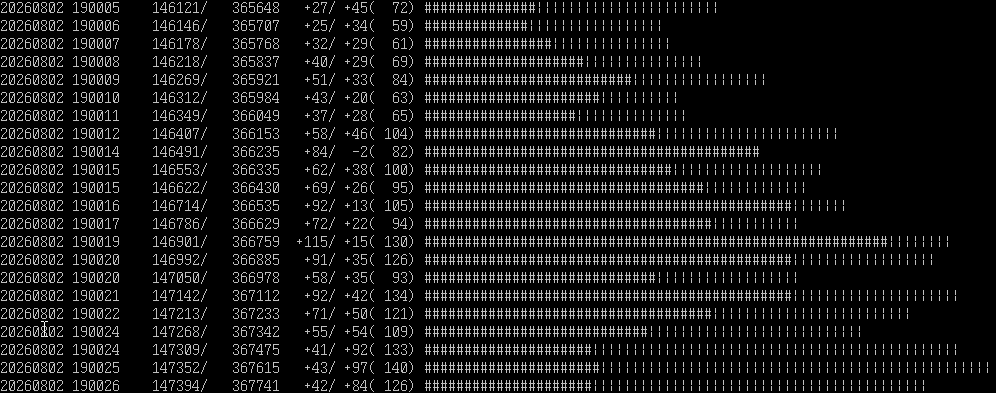
Here’s a bit of a graph from the TCRF server, one of the analysis tools I made and use. It simply shows a running count of “how many accesses were made to the web server this second”, split across blocked accesses (403s, indicated with a “#” on the bar) and all others (indicated with “|”). This is right as one of the DDoS waves came in, and you can see things jump from TCRF’s stable “5-15/sec” to nearly 100:

This particular DDoS has been ongoing since early January in various forms, and as far as I can tell seems to be targeted at us directly. Thousands of IP addresses, all making one or two requests, all at the same time.

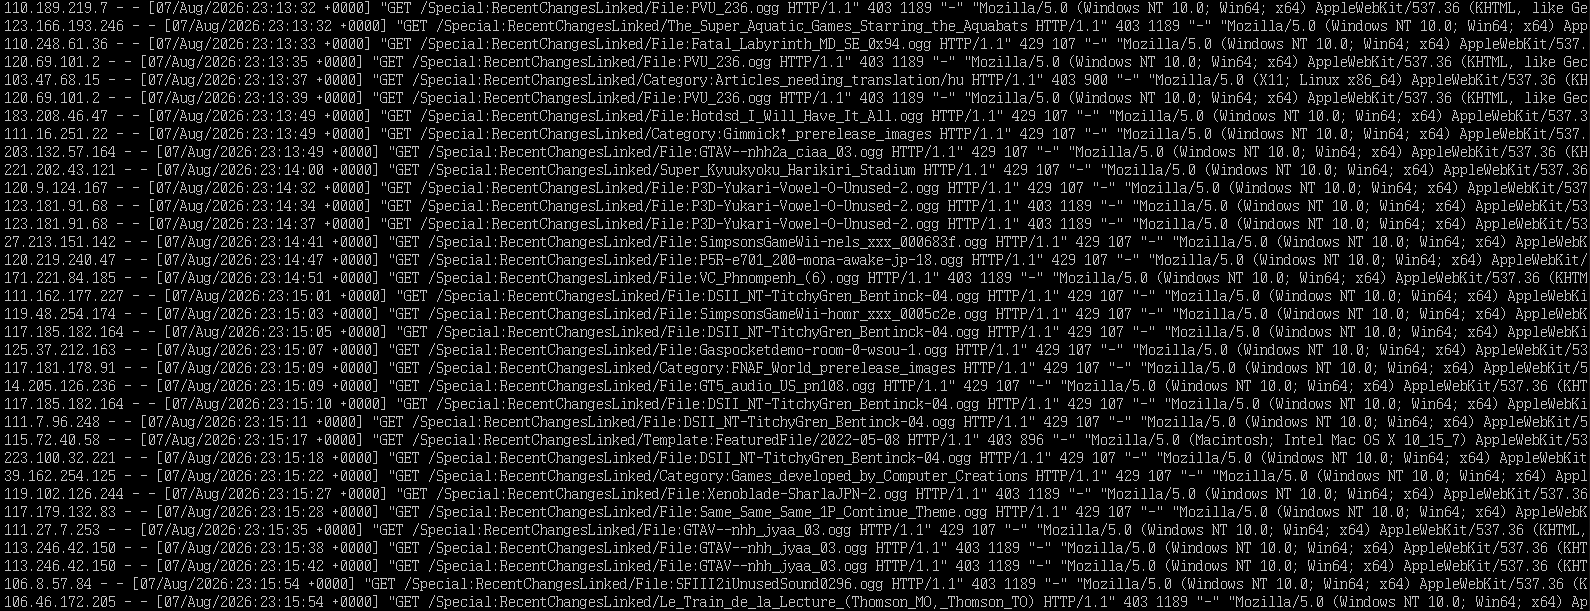
These attacks typically last for a minute or two. The bots have certain pages and features that they disproportionately target: “expensive” pages to generate. For the first few months — before I’d actually pinpointed it as a DDoS — they mostly focused on making excessive calls to “Special:RecentChangesLinked“, a page that shows a page’s history and the history of every page linked to it. By simply requesting 5,000 different pages’ worth of interlinked history, the server grinds to a halt and nobody else can access a page.

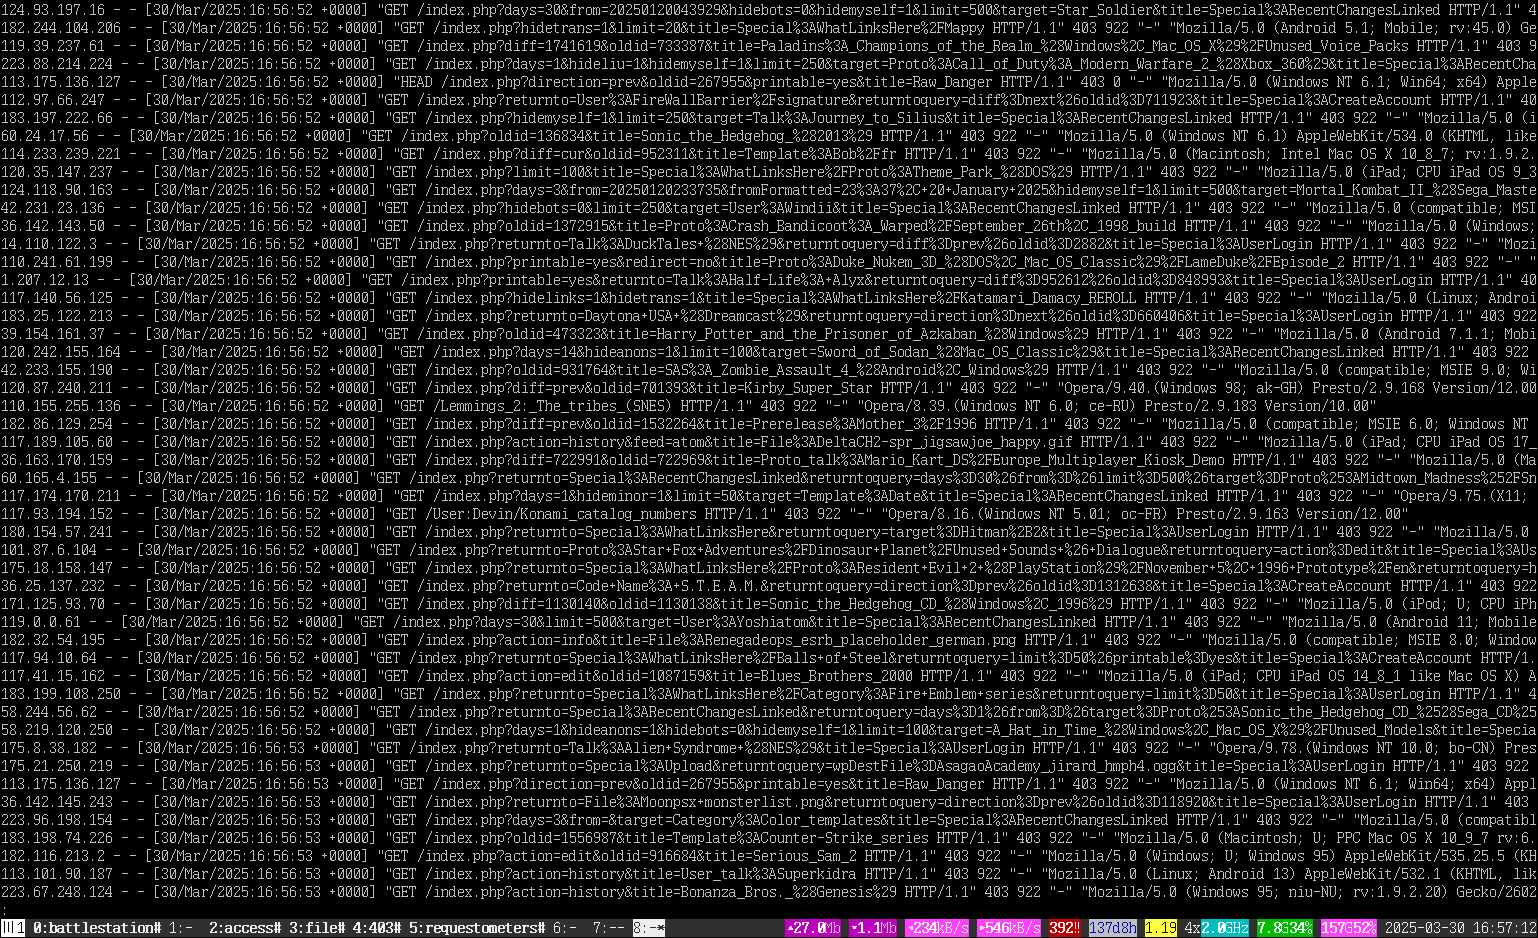
When that attack was mitigated by making RecentChangesLinked login-only, The next attack has largely focused on just blasting random history / comparison pages, again with the strategy of “spend as much time executing worthless requests as possible so that nobody else can get in”. Note that almost all of these are within the same second, and from a wide variety of IP addresses, almost all Chinese-based:

It’s not as useful to attack a basic content page, because the wiki will simply give you the cached version. So the bots go after these deep, dynamic pages to waste resources.

Stopping the insanity

Stopping the attack on the site has been an ongoing process, employing multiple methods.

One tool that cropped up recently and got remarkably popular is Anubis, a service that sits in front of your webapp and presents connecting users with a challenge. The challenge effectively requires a client to waste several seconds/minutes doing expensive-to-do but easy-to-verify math, under the idea that bots won’t waste time doing it (if they are even using a client capable of handling it). Anubis seems great, but isn’t really workable for TCRF for a few reasons:

  • It requires Docker, which TCRF doesn’t use, and which I don’t want to have to learn, stand up, and add to an already-exhausting maintenance load
  • It requires you to use nginx as a reverse proxy to a “web app”; TCRF uses nginx as a web server, not a web app, so there is nowhere to slot it in without standing up even more services
  • It presents its challenge to everyone

If you’re setting up a modern web app, by all means, but the costs of implementing it here are too much.

Another suggestion that has cropped up is Cloudflare. Cloudflare likely needs no introduction: they’re a content-delivery-network that you place in front of your web server, and as part of their services they offer anti-DDoS protection. The problems with Cloudflare mostly stem from disagreeable politics, not wanting to rely on an external third party, and (again) having to set up something else in the middle that breaks all the workflows. And, again, I’m not the biggest fan of putting an interstitial in front of every single person.

So, what do you do?

Before analyzing the logs and determining that a lot of the abuse was coming from one particular location (China), the first step was simply to limit access to the most expensive pages. Since this is a simple PHP site, I was able to do this by just inserting a bit of magic into the index page; you might be able to see it if you go directly to one of the blocked pages in an incognito tab. It’s not the best, but it’s short, simple, and (most importantly) prevents the server from wasting additional resources on the request. Logged in users never get this message.

Your request was blocked. Try disabling any VPNs or proxies and try again. If problems persist, please get in touch via Discord (https://discord.gg/wnfBf5D) or IRC (irc.badnik.zone #tcrf, slow)

Then: block. Block block block. So far, most of the problem has come from a handful of networks, or ASNs. They use many IPs within those networks, but they’re still from that network. So: Block ’em all!

As a live example, one of thousands of the malicious IPs was from “219.142.153.182”. A quick look at ipinfo gives us little reason to be surprised: it originates in China, a common theme for these bots. So, simply take the AS number, “AS4847”, throw it into asn.ipinfo.app, and presto, a blocklist ready to drop into nginx. Do this about 20 times, and the DDoS starts to run out of networks it can abuse you from.

The full list of network blocks on TCRF is long and only getting longer, but it includes a frustrating number of Chinese-based telecoms, mobile networks, and cloud providers, especially Alibaba. Holy shit Alibaba is one of the most abusive networks I have ever seen, and I’m not lying when I say any sysadmin’s first step should be routing it to a black hole.

The advantages of all this is that, for most users, it’s completely transparent. Anyone can still use any old browser (even on Windows 98), there’s no intrusive waiting pages or CPU-melting Javascript challenges. The downsides are that innocent users can (and will) get caught up in these blocks, and since not everyone is subjected to the methods, there are ways to bypass it.

But at the end of the day, it’s extremely effective, and even with 100 requests/second, the requests being blocked means it doesn’t even cause a blip on the server.

And yes, there were DDoS waves hitting the server even as I was writing about it. For now, the attacks are impotent.

Here’s a Bluesky post with a video of what the access log looks like when it happens (about 15 seconds in):

i wanted to record a video of what it *normally* looks like, but of course this bozo had to fuckin interrupt it

— X ΘΔ (@xkeeper.net) 2025-03-30T19:13:55.838Z

Running TCRF is a one-person operation. If you’d like to support us, please consider joining our Patreon. You can also support me directly via Ko-fi.

Hopefully, there’s a day in the future where this comes to an end.

Ping chart code

I mentioned in the previous post about my DIY network monitoring that I’d put the code up eventually, and that time is (or was) now. It’s still not really cleaned up, but if you want to run it, you can do that now.

It requires fping, which is a tool you should be able to install from your package manager. It’s basically ping but with slightly better output for script use.

Anyway: pingchart (GitHub)

DIY Network Monitoring

I’ve been posting images on Twitter and elsewhere lately that are largely green squares with red dots on them. While I intend to write a longer post on that later, for now, I’ll make a quick explanation of them.

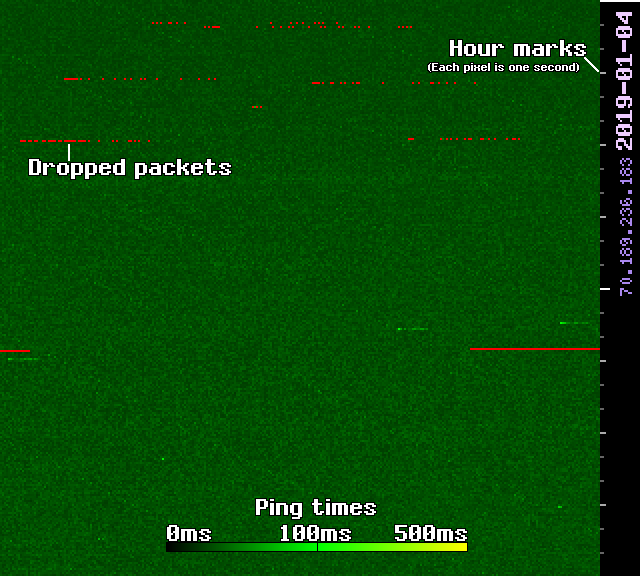
A sample image from January 4th is below; there is also a webpage with an updated display of them.

A typical ping chart from my tool, with a large block of green pixels dotted with red. The green pixels show the ping response time (in ms), red dots are dropped packets, and each image represents one day with each pixel representing one second.
These are quite good at showing weird network behavior and other anomalies, but not good for diagnosing why.

Each pixel represents a test done on one second; each row is 300 pixels, or 5 minutes. Seconds go from left to right, top to bottom, and hours are ticked off by marks along the right edge. Faster times are denoted with darker greens, getting lighter as they approach 100ms, and turning yellow as they reach 500ms. Packets that aren’t received within half a second are marked lost, and show up in red.

Ideally, I wouldn’t have had to make this tool, but we’ve had three different cable technicians inspect our equipment with no improvement, and we’ve also purchased a newer modem. While the new modem helped, it’s only because it’s able to achieve even more out-of-spec power levels, and not because the old one was faulty.

Unfortunately, we haven’t managed to correlate this to anything going on inside or outside our apartment, so all we can do is monitor what’s happening for now… and use it as further evidence that the problem still isn’t fixed.

Cable modems are garbage

We’ve been having a lot of internet issues at the Romhaus, the subject of which will have to be a topic for another post.

While we’ve been trying to get it fixed, one of the things that was recommended to us by Cox was purchasing a new modem to replace our old (but still otherwise functional) Arris Surfboard, as it supported only DOCSIS 3.0 and was a few years old. We decided to replace it with a shiny new Motorola MB8600, which was the only DOCSIS 3.1 modem we could find nearby. (Unsurprisingly, it didn’t help, so that was a cool $160 we spent on not fixing the problem.)

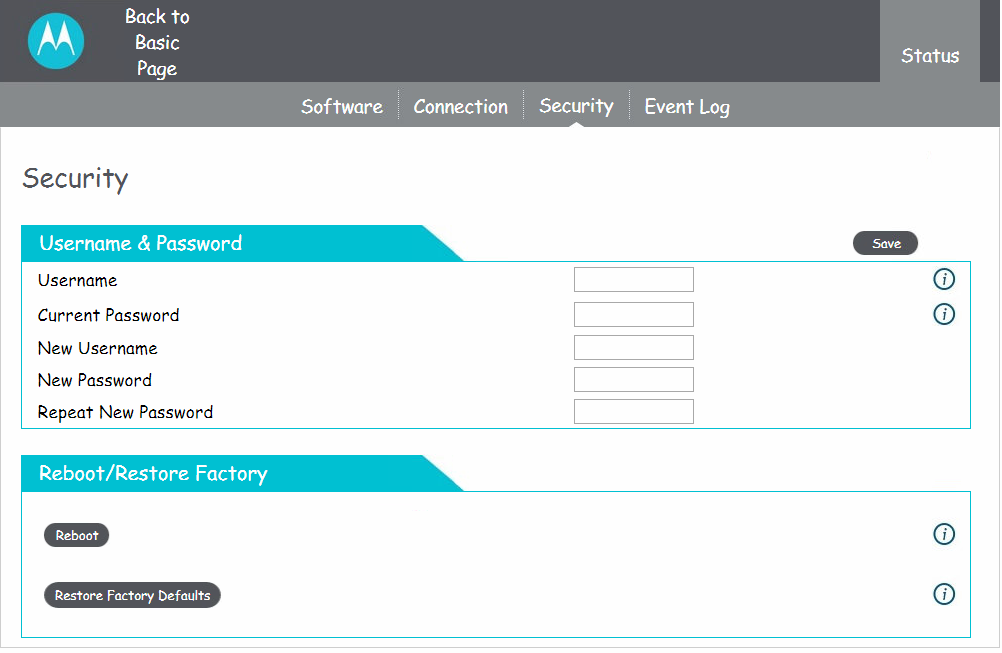
While the old modem had no authentication, it also didn’t pretend to. There also wasn’t anything you could actually do with it — it was strictly a view-only interface, as far as I remember. The Motorola instead requires a username and password to log in. Logging in allows you to reboot the modem, restore it to factory defaults, or change the username and password.

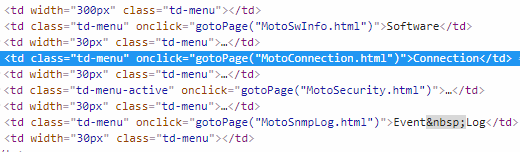
DevTools screenshot of the top menu elements, showing that they are table cells with onclick events instead of actual links.
why

The entire interface is a mess of Javascript in place of meaningful HTML; rather than using normal links, everything is based on onclick events. The layout is built on tables within tables within tables, even in places where it isn’t useful (for example, the header of each table is itself a table, with the green-to-white transition provided by an image). There’s no reason for any of this, and it’s usually a sign of bad design further down.

And of course it is. As part of my network monitoring, I wrote a script that checks the connection status page and extracts the power levels, to help diagnose our ongoing issues. With the old modem, it was just a matter of requesting the status page; with the new one, that’s behind a login page, so I had to figure out how to have the script log itself in.

Beyond the login form being a further mess of needless JavaScript (you don’t need onBlur and onFocus if you just use ::placeholder like normal people), I dug through the login page to figure out how, exactly, it logged you in. And of course. Of course it’s horrible.

function btnApply() // (Called when you hit submit)
{
   var loc  = '/login_auth.html?';

   with ( document.forms[0] ) {
      loc += 'loginUsername=' + encodeUrl(loginUsername.value);
      loc += '&loginPassword=' + encode(loginPassword.value);
      loc += '&';
      var code = 'location="' + loc + '"';
	  
      eval(code);
   }
}

aaagh

What this does, in human terms:

  1. URL encodes your username.
  2. base64-encodes your password.
  3. Glues those together into a URL, “/login_auth.html?loginUsername=(url-encoded username)&loginPassword=(base64-encoded password)&“
  4. Prepends a JavaScript fragment to redirect you to that URL and executes it.

Yeeeep, it sends it over GET, completely in the clear. Making the script log in after finding this out was trivial.

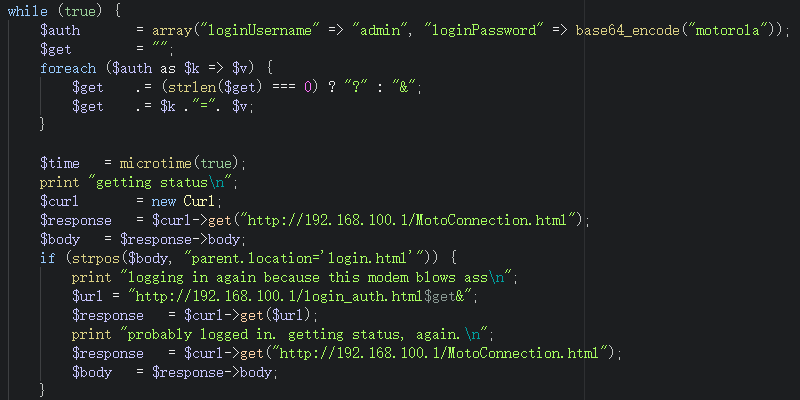
A snippet of code showing how the script logs into the modem by doing a simple GET request with the username/password query parameters.
And somehow this isn’t even the worst part

That’s bad enough, but there’s more. Because of course there is.

When I first started developing this, I didn’t need to log in at all. It turns out that — surprise! — logging into the modem authenticates it for everyone. If you log into it on Computer A, and then open the modem page on Computer B, you’ll be presented with the information screen, without needing to log in again. At first I thought it might be a fluke or based on IP addresses, since I had the page open in my browser as well, but after letting the script log in, I opened the modem page on a computer in another room that hadn’t been touched for hours and, well, I didn’t have to log in.

So you don’t even need to sniff the password; you just need someone to log in for you.

I hate computers.


UPDATE!!! As pointed out in the comments, the current usernames and passwords are straight up dumped in plain text in the Security tab. I can’t even make this shit up, oh my god.

Snippet of the page source for the security tab, showing the current usernames and passwords for the modem's accounts
SERIOUSLY YOU GUYS

dfasgfdvcdfllghkfdsghk

Jul, a forum

Jul‘s a forum I run. If you’ve been around me for a while, you’ve probably heard of it. It’s a fork of an ancient forum, both in the sense of community (from Acmlm’s Board) and software (Acmlmboard). They were created by (surprise) Acmlm back in early 2001, 18 years ago. The community went through a lot of… turbulence over the years, branching into several different, smaller communities, before mostly settling down around 2010.

While a full genealogy chart is a little much for the first post about it, especially at 11:40 PM, there are a lot of variants and forks of the code, as well as several attempts to recreate it. Jul runs on a version that’s more similar to the original than most modern ones, though.

As most of the internet has moved on to social media like Twitter and Facebook, forums have been left behind. They’re simpler, they’re not centralized, and they’re a lot more relaxed. Forums aren’t going to send you push notifications or flood your e-mails or shove a bunch of recommendations in your face, and for that they fall behind the “engagement” metric… but as a long-form place to organize, discuss, and just hang out? Can’t beat them.

The code Jul uses is on GitHub, though it’s still full of Jul-specific hacks features and isn’t really usable on its own. It has no installer or readme, no guides, and is, frankly, a mess. Even then, it still manages to run, over 18 years after it was first made! Pretty impressive.

One of Jul’s more notable features — shared with other Acmlmboard-likes — is the ability to make “post layouts”. Unlike typical forum signatures, post layouts (and posts themselves) can include full HTML, both before and after a post, letting you flair your posts with a touch of style. Of course, users can also disable those by default if they’re too obnoxious.

Anyway, this post was brought on because I did some updates to it, mainly in redesigning the new reply page:

New Reply page for a user not logged in, showing an invalid username/password error next to the username field
The new reply page now simply shows an error if you’re logged out and give an invalid username or password, instead of cancelling your post entirely. Of course, if you post while logged in, you never see this.

The changes are fairly minor, but hopefully make it nicer to use:

  • “Mood avatars” are a dropdown instead of a large list of radio buttons
  • Posting while logged out and putting in an invalid username/password will return you to the form, without losing your post
  • Internally, the code is cleaner and better organized
  • The post reply box can now be resized fully, instead of being locked to 800px wide
  • Post previews now use the same form as the initial reply, instead of a separate one (for some reason)
  • In the event that you aren’t able to post your reply (because e.g. the thread was closed or moved to a restricted forum), you’re given a chance to copy what you had written — you no longer instantly lose it
An error when replying caused by the thread being closed. There is a textbox under the error with the content of the post that was being written, letting the author copy and paste it elsewhere.
The days of typing a long monologue only to lose it are (hopefully) over.

It’s a neat place! You should come visit some time.